How to Monitor Claude Code Sessions, Tool Calls, and Token Usage
Once a team uses Claude Code every day, two sessions that look alike can differ in cost by ten times or more. When the invoice arrives and someone asks what the spend bought, the data to answer is in three places that don't connect: terminal history shows commands but not why they ran, git shows the diff but not the session behind it, and provider billing shows totals with no session, repo or team.
This post shows how to treat each session as a trace, the patterns that make sessions expensive, and a weekly review that turns the data into fixes.
A session is a trace
One coding task produces a tree of model calls, tool calls (reads, edits, searches), terminal commands, subagent handoffs and retries. Each step uses tokens and carries context about what the agent was doing.
flowchart TD
    S["<b>Session</b><br/>one coding task<br/><i>developer · repo · branch · model</i>"]
    S --> M["model calls<br/><i>context growth</i>"]
    S --> TC["tool calls<br/><i>read · edit · grep</i>"]
    S --> TERM["terminal commands<br/><i>tests · builds</i>"]
    S --> SUB["subagent<br/>handoffs"]
    M --> OUT["<b>tokens + cost + outcome</b>"]
    TC --> OUT
    TERM --> OUT
    SUB --> OUT
    style S stroke:#f4ae30,stroke-width:2px
    style OUT stroke:#59ca6f,stroke-width:2px
Seen this way, cost per seat is the wrong unit. The same amount can be one long productive session or thirty short failed ones. What you want is cost per session, with the session's shape next to it.
Five patterns behind expensive sessions
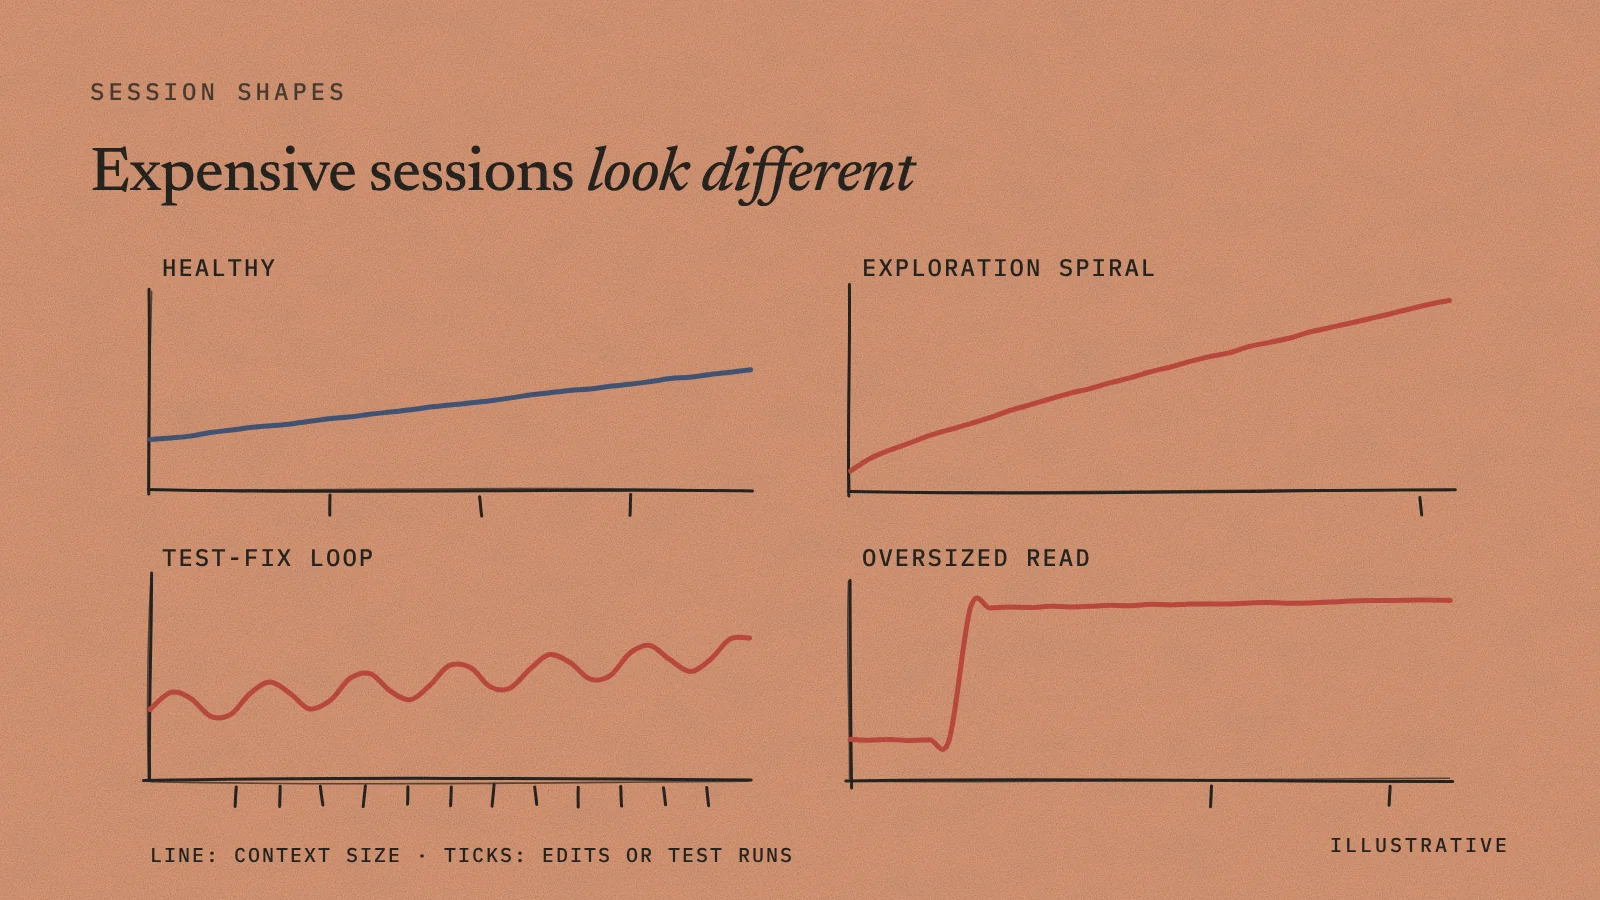
| Pattern | What it looks like in the trace | Fix it in the environment |
|---|---|---|
| Exploration spiral | Many reads and searches before the first edit; context grows on every call | A CLAUDE.md with a repo map, clearer module boundaries, narrower task prompts |
| Test-fix loop | Repeated test runs with small edits in between; fine at three rounds, not at fifteen | Fix flaky tests, make failure messages specific, add a fast local check |
| Oversized read | One large file or log enters context and is carried on every later call | Split large files, exclude generated output, summarize logs before reading |
| Permission friction | Repeated failed or denied commands | Fix the environment and allowed commands before blaming the model |
| Model escalation | Sessions switch to a larger model with no better outcome | Agree on when the larger model is worth it and review exceptions |
Most of these fixes are to the codebase and the developer environment, not the prompt. A coding agent explores your repo all day, so its loops point at missing docs, confusing structure and flaky tests. Fixing those helps human developers too.
Set it up
Create an endpoint of type Claude Code & Codex CLI in the console, copy its API key from Collecting → Integration Options → API, and install the hook on each machine:
Or with Node.js: npx -y anosys-sdk-claude-code install.
The installer asks for:
- The API key from the endpoint.
- An OTEL key (optional), to also turn on Claude Code's built-in OpenTelemetry export.
- Content redaction: when on, prompts, responses and thinking are replaced with
REDACTEDbefore they leave the machine, while tokens, cost and metadata are still sent. Use it if your policy allows usage data but not conversation content.
It adds an Anosys Stop hook to ~/.claude/settings.json (after backing it up). At the end of each turn the hook reads the new part of the local transcript and sends it. For dotfiles or a fleet rollout, the same command takes --api-key, --otel-key, --redaction and --auto-update flags. Run anosys-claude-code status to check it.
Each session then arrives with tokens (including cache reads and writes), estimated cost per model, tool calls, shell commands, files written, subagents, and the developer, project, branch and Claude Code version.
A weekly review that produces fixes
Once a week, take thirty minutes:
- Sort sessions by cost and open the top ten traces.
- Label each with a pattern from the table above, or "worth it" if it was a large task done well.
- Group by repo. Patterns usually cluster: one repo with flaky tests, one with a huge generated file.
- File one backlog item per cluster: document this boundary, fix this test harness, exclude this directory.
- Check last week's items by comparing that repo's cost per session before and after.
The review should end with backlog items, not with "Claude is expensive."
Useful alerts, sent to the team that owns the repo rather than to everyone:
- a session above a cost threshold
- a session with more than N test runs
- a jump in average cost per session for one repo
Free plan, no credit card
Start monitoring Claude Code for free
See sessions, tool calls and token cost per repository and developer in a few minutes, using Claude Code's built-in telemetry.
Related
- Claude Code documentation, including the built-in OpenTelemetry option
- Track AI and coding spend across Claude Code, Codex and other tools
- How to attribute LLM cost to agents, users and workflows

