What Is AI Operational Intelligence?
A customer success manager reports that the support assistant "feels worse." Latency is normal, error rates are flat, and last month's eval suite still passes. In the same week, finance asks why the model bill grew 40% in three weeks. Nobody can say whether the two are related, because the evidence is spread across five tools owned by five teams.
They usually are related. AI operational intelligence is the practice of running production AI with enough connected evidence to answer four questions quickly: what happened, why, who it affected, and what to do next. Observability tools answer the first. Most production time goes into the other three.
Why healthy dashboards miss AI problems
Traditional monitoring assumes that if a service is up and fast, the customer is fine. AI systems break that assumption: they keep responding while the value of the responses drops.
- An agent returns a fluent, confident, wrong answer.
- A prompt edit lowers task completion while the model stays fully available.
- A support assistant meets every technical SLA while escalations to human agents climb.
- A coding agent finishes every run but uses three times the tokens, because a tool started returning a format the agent retries around.
None of these is an error. All of them show up in the business. And the cause is as likely to be a release, a tool change, a data shift or a new group of users as the model itself, so watching the model layer alone doesn't find it.
Put the signals on one timeline
Most teams already collect traces, logs, eval scores and billing exports. What's missing is putting the signals about one behavior side by side: the model calls next to the tool calls they made, the release that shipped an hour earlier, the token spend of the affected sessions, and what users did afterward.
The signals that matter:
| Signal | Why it matters |
|---|---|
| Traces and spans | The agent's actual path through a run |
| Tool calls and handoffs | Where agents loop, stall and delegate badly |
| Eval scores | The only direct measure of answer quality |
| Token and model cost | Attributed to workflows and users, not one monthly number |
| Application and infrastructure telemetry | Many "AI failures" start outside the AI |
| User behavior | Abandonment and escalation are early, honest quality signals |
| Business events and KPIs | The reason the system exists |
Each is familiar on its own. Connected, they turn an investigation from "open six tabs and build a theory" into "follow one timeline from symptom to cause." In the support assistant case, the timeline shows that resolution rate fell for enterprise accounts after Tuesday's release, that the drop lines up with a CRM tool that started retrying, and that the retries also explain the token spend finance asked about.
The same question, asked by every team
| Team | What they need to know | Evidence |
|---|---|---|
| Engineering | What broke, and where in the run? | Traces, tool calls, logs, release markers, infrastructure |
| ML and AI engineering | Did the model, prompt, retrieval or eval results change? | Model and prompt versions, eval scores, retrieved context |
| Product | Did users get a worse outcome? | Sessions, abandonment, task completion, escalation |
| Finance and operations | Which workflows produce useful spend? | Tokens and cost by user, account and outcome |
| Governance | Can we show controls ran in production? | Owners, policy checks, redaction events, audit trail |
If answering these takes five tools and a meeting, the team has telemetry, not operational intelligence.
A maturity model
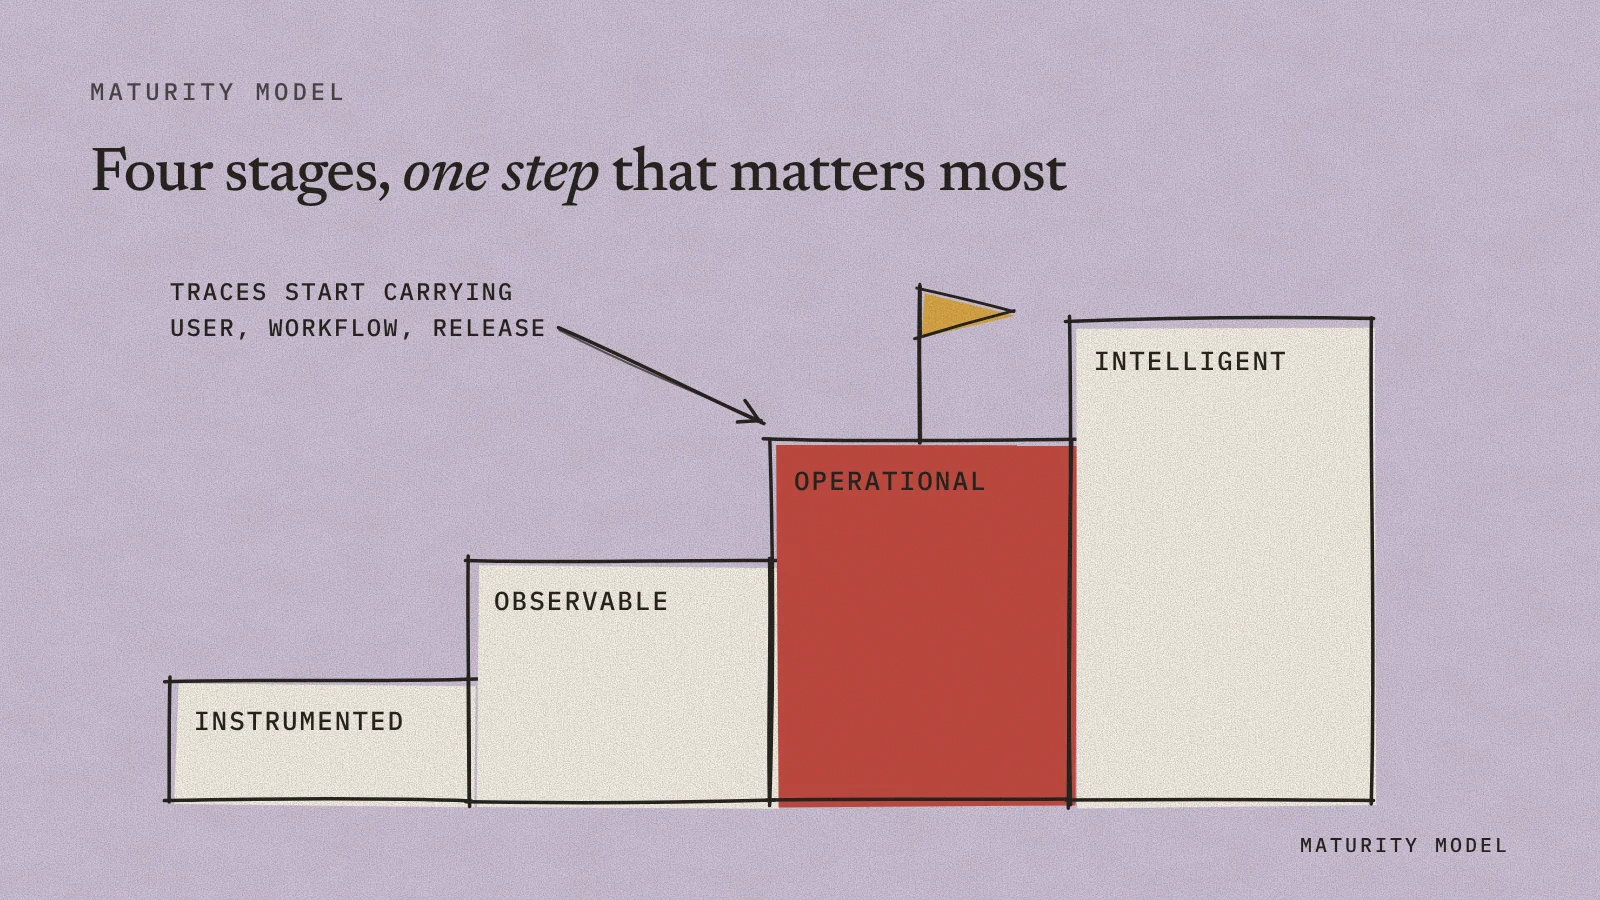
| Stage | What the team has | What is still missing |
|---|---|---|
| Instrumented | Model calls, logs, basic token counts | Business context and owners |
| Observable | Agent runs, tool calls, evals, latency, failures | Joins to users, cost and outcomes |
| Operational | Traces tied to cost, releases, users, KPIs and alerts | Governance and follow-through are still manual |
| Intelligent | Cause, affected users, owner and next action in one view | Nothing structural; the loop runs continuously |
The step that matters most is from observable to operational. That's when a trace stops being a debugging artifact and becomes an operating record, because it carries the IDs (user, session, workflow, release) that connect it to the rest of the business.
Where to start
Pick the question your team can't currently answer with evidence:
- Are customers getting worse outcomes while systems look healthy?
- Is token spend growing faster than usage?
- Which agent failures come from tools and releases rather than the model?
- Can you explain a quality drop after a prompt change, and show a reviewer which controls applied?
Instrument what that one question needs, and add the next signal when the next question needs it.
How Anosys does it
flowchart LR
    A["<b>Collect</b><br/>traces · evals · cost<br/>users · process events"] --> B["<b>Connect</b><br/>one timeline,<br/>shared IDs"]
    B --> C["<b>Explain</b><br/>cause and<br/>who was affected"]
    C --> D["<b>Act</b><br/>alerts · owners<br/>pipelines"]
    D -. "the fix produces new signals" .-> A
    style A stroke:#59ca6f,stroke-width:2px
    style B stroke:#4ea3ff,stroke-width:2px
    style C stroke:#e076b8,stroke-width:2px
    style D stroke:#f4ae30,stroke-width:2px
Anosys collects these signals through agent SDKs, OpenTelemetry, a REST API and a website and product tracker, and maps your IDs once so they work across all of them. Traces, evaluations, cost views, the AI Assistant and alerts all read from the same data, so the engineer debugging, the analyst forecasting spend and the reviewer checking controls are looking at the same evidence.
For the agent-specific version of this argument, see Why AI observability is not enough for production agents. For cost, see How to attribute LLM cost to agents, users and workflows.
Explore the Production AI Operations solution or start with Getting started.
Free plan, no credit card
Put traces, cost and outcomes in one place
Connect your AI apps and see quality, cost and business results side by side, with alerts when any of them moves.

