Why AI Observability Is Not Enough for Production Agents
If you run agents in production, you need observability. A system whose core behavior is "a model decided something" can't be operated without seeing prompts, completions, tool calls, handoffs, retries, latency and eval scores.
Teams that have good agent tracing still run into the same wall, though. In an incident channel, someone posts the trace of the failing run, and then the real discussion starts. Which customers hit this? Did it change support volume? What did the retries cost? Is it a compliance problem? Who owns the fix: the agent team, the platform team, or whoever changed the upstream API last night?
The trace answers none of that. Those questions need context from product analytics, billing, release history and ownership records. This post is about that gap, and how to close it for agents specifically. The broader argument is in What is AI operational intelligence?.
Agents fail sideways, not down
A service usually fails down: errors, timeouts, crashes. Monitoring was built to catch those. An agent more often fails sideways, through runs that technically succeed:
- It calls the right tool with slightly wrong parameters and gets a plausible result.
- It retries a flaky endpoint until spend triples, then succeeds.
- It hands off to the wrong subagent, which does the job worse and slower.
- It answers confidently from stale context.
- It passes the relevance eval while the metric the workflow exists for (conversion, resolution, time saved) goes down.
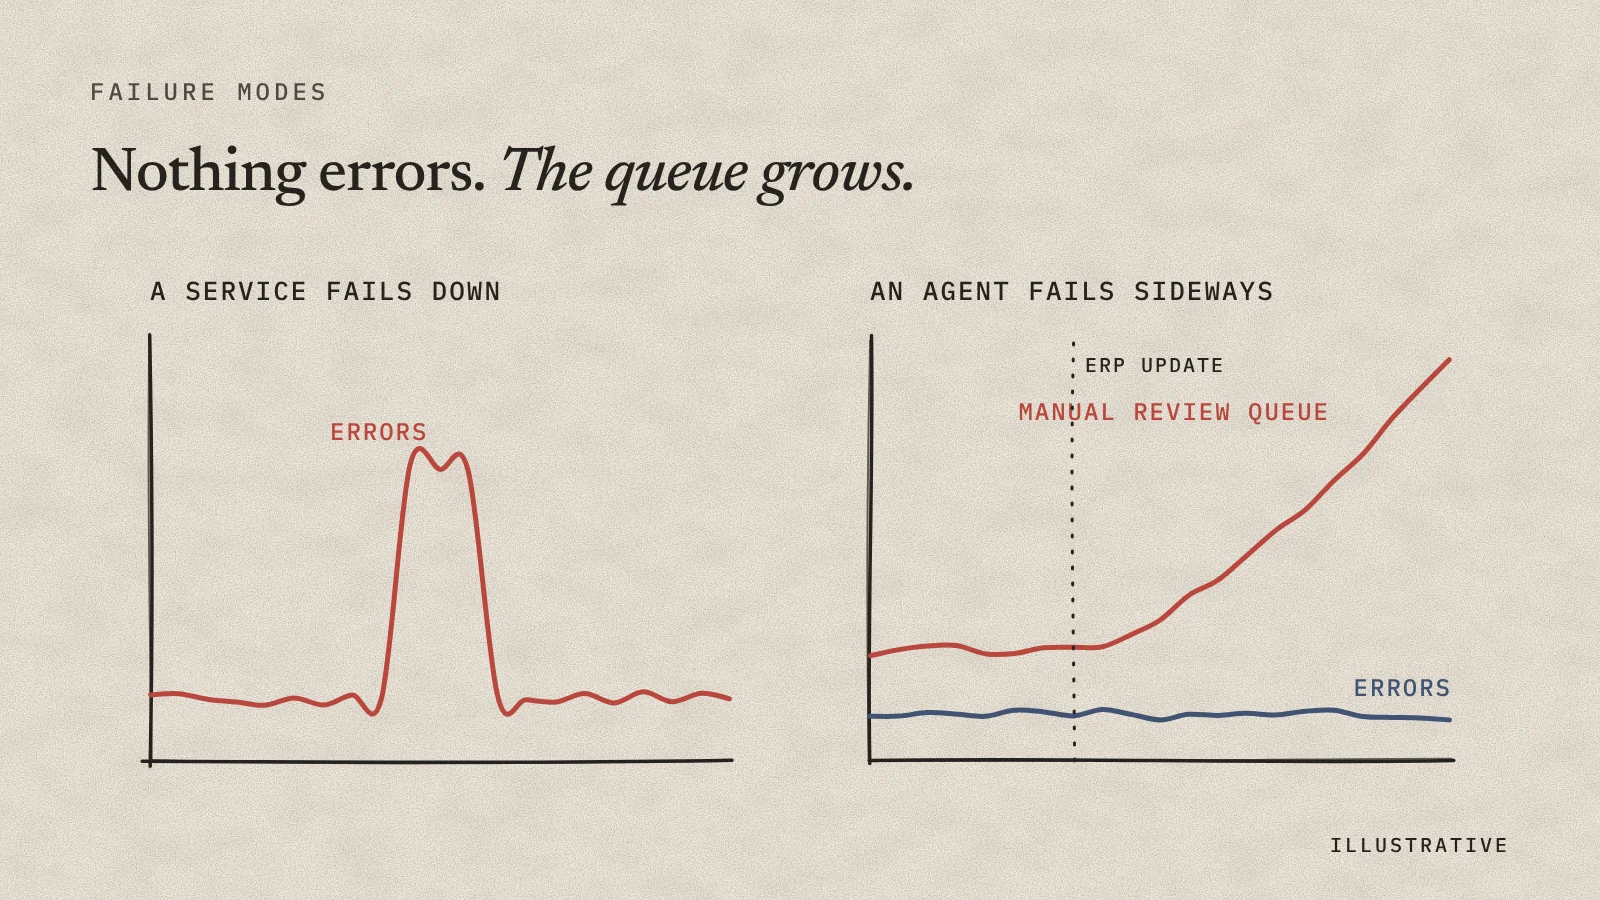
Each of these produces a trace that looks fine on its own. The problem only shows when the trace sits next to a baseline, a cost line, an eval trend and a business outcome.
An example
An accounts-payable agent reads supplier invoices, matches them to purchase orders through an ERP tool, and queues them for payment. One Monday, the share of invoices sent to manual review doubles.
With traces alone, an engineer sees more calls to the match_po tool and slightly higher latency. Nothing errors. With the surrounding evidence, the picture is clear within the hour:
- Release history: nothing on the agent changed, but the ERP team shipped an API update on Friday.
- Tool calls: since Friday,
match_poreturns dates in a different format, and the agent re-queries with different parameters two or three times per invoice. - Cost: tokens per invoice rose about 60% on those runs.
- Business outcome: invoices that fail matching go to manual review, so the AP team's queue doubled and some early-payment discounts were missed.
- Evals: answer-quality scores stayed flat, because the agent's final summaries were still accurate.
The diagnosis came from the joins: trace to release, trace to cost, trace to the business outcome. And the evals passing throughout is the uncomfortable part: a quality check on model output can't see a failure whose cause is a tool contract and whose impact is a queue in another team.
flowchart LR
    TR["<b>The trace</b><br/>what the agent did"]
    TR --> REL["+ releases<br/><i>what changed</i>"]
    TR --> COST["+ cost<br/><i>what it spent</i>"]
    TR --> USR["+ users and teams<br/><i>who felt it</i>"]
    TR --> KPI["+ business outcomes<br/><i>whether it mattered</i>"]
    REL --> RC["<b>Cause</b><br/>+ owner + severity"]
    COST --> RC
    USR --> RC
    KPI --> RC
    style TR stroke:#7c4dff,stroke-width:2px
    style RC stroke:#59ca6f,stroke-width:2px
Test your stack with a tabletop exercise
To find out whether your current setup is enough, walk through these incidents and write down what you could answer today:
| Incident | What a trace answers | What you also need to know |
|---|---|---|
| Agent latency doubles | Which span was slow | Whether users abandoned, which workflow is affected, and whether the cause is model, tool, queue or release |
| Token spend jumps 40% | Which calls used tokens | Which agent, customer segment, tool result or retry pattern caused it |
| Evals flat, conversion falls | The output still scores well | That the workflow outcome dropped even though answer quality didn't |
| A tool returns malformed data | Error or retry count | Who owns the tool, which accounts were affected, the downstream impact and the rollback path |
| A policy violation in production | The offending output | The prompt, model, user context, redaction state, owner and audit trail |
What to record beyond the trace
The minimum useful record for an agent run:
- Stable IDs: workflow, user or account, team, environment, release.
- Versions: model, prompt, and tool or API version where you can get it.
- Cost: tokens and cost on every model call, not only a monthly provider export.
- Evals: results attached to the run they scored.
- Outcome events: completion, abandonment, conversion or escalation, sent with the same run or session ID.
A sensible order to build it: capture full runs first; add evals for quality and task success; attribute cost by agent, workflow and customer; connect runs to releases and business events; then invest in alerting. Alerts on connected evidence tell you about outcomes. Alerts on raw telemetry mostly tell you about noise.
How Anosys closes the gap
Anosys captures full agent traces (prompts, model calls, tools, handoffs, retries) from the agent SDKs and OpenTelemetry, and keeps the rest in the same workspace: cost per session and workflow, evaluation results tied to runs, application events, user behavior from the tracker, and your own business events. Because the IDs are mapped once, the example above is a set of filters on one dataset rather than four exports. Alerts can go to the owner of the failing step, with the trace and the affected accounts attached.
Start with the Traces documentation or the AI Agent Debugging solution.
Free plan, no credit card
See what your agents actually did
Full agent traces plus the cost, evals, app events and outcomes around them, in one workspace.

