How to Govern Production AI Without Slowing Teams Down
Most AI governance programs do not become bottlenecks because governance is inherently slow. They become bottlenecks because organizations ask a committee to compensate for decisions that should have been made in the product architecture.
A team wants to change a customer-support agent. Security asks what data it can access. Legal asks whether it can make commitments to customers. Risk asks how its outputs were evaluated. Engineering opens five dashboards, reconstructs the release by hand, and waits for three people to approve a document that will be stale after the next deployment.
The predictable response is not better governance. It is avoidance. Teams relabel material changes as “minor,” experiments linger outside the inventory, and the official record drifts away from the production estate.
AI governance in production is the system of decision rights, technical controls, evidence, and operational processes used to keep an AI use case within its approved purpose and risk limits throughout its lifecycle. Done well, it gives routine changes a paved road and reserves scarce human judgment for decisions with real consequences.
The point is not to remove friction everywhere. A system that recommends internal documents should move faster than one that changes a customer’s account, screens a job applicant, or writes to production infrastructure. The point is to put friction where authority and potential harm justify it—and automate the rest.
Start with the use case, not the model
“We use model X” is not a risk assessment. Neither is “this is an agent.” The same foundation model can summarize an approved internal document, recommend a refund, execute the refund, or coordinate other agents that act across several systems. Those deployments do not deserve the same controls.
OpenAI’s governance paper treats agenticness as multidimensional: it depends on goal and environmental complexity, adaptability, and the degree of independent execution—not on a binary agent/non-agent label (Shavit et al., 2023, pp. 4–5). Stanford’s operational classification similarly considers actions and tool access, decision influence, external exposure, autonomy, data sensitivity, and reversibility, and calls for classification to change as capabilities change (Stanford University IT, “Agentic AI Risk Classifications”).
That distinction matters in production:
- A predictive model estimates or classifies, such as forecasting demand.
- A generative assistant drafts or recommends while a person remains the actor.
- An agentic system plans, invokes tools, and takes actions toward a goal with limited supervision.
- A multi-agent system introduces interactions among agents, including dynamics that may not appear when each component is tested alone.
The last category deserves particular care. The multi-agent literature identifies possible risks from coordination, collusion, conflict, correlated behavior, and emergent network effects, while also emphasizing that evidence for several advanced scenarios remains limited and that better real-world evaluation is needed (Hammond et al., 2025, pp. 4–5, 16–19). That is a reason to test interactions, not a reason to treat every chatbot as a frontier threat.
flowchart LR
    P["<b>Predictive model</b><br/>estimates or classifies"]
    G["<b>Generative assistant</b><br/>drafts or recommends"]
    A["<b>Agentic system</b><br/>plans, uses tools, acts"]
    M["<b>Multi-agent system</b><br/>interacts and coordinates"]

    P -->|"more decision influence"| G
    G -->|"more action authority"| A
    A -->|"more interaction complexity"| M

    style P stroke:#4ea3ff
    style G stroke:#2dc5c3
    style A stroke:#ad7aeb,stroke-width:2px
    style M stroke:#ee8d3a,stroke-width:2px
Figure 1. A deployment continuum—not a universal ranking of model risk. Original synthesis informed by Shavit et al. (2023, pp. 4–5), Stanford University IT, and Hammond et al. (2025, pp. 4–5).
The governance object, then, is the deployed use case: model, prompts, data, tools, permissions, users, operating environment, and consequences together.
Use risk tiers to create more than one path to production
A common pattern is a single review path designed around the organization’s most sensitive use case. It is then applied to everything. This sounds defensible on paper, but it creates two problems: low-risk work queues behind high-risk work, and reviewers waste time repeatedly confirming that routine systems are routine.
A proportionate operating model creates at least three paths:
| Dimension | Low risk: accelerated path | Moderate risk: targeted review | High risk: enhanced assurance |
|---|---|---|---|
| Data | Public or approved internal data | Confidential business data with bounded access | Regulated, highly sensitive, or rights-relevant data |
| Decision role | Informational; no material decision role | Recommends or influences a reversible decision | Determines or materially shapes a consequential decision |
| Tools and permissions | No tools, or read-only approved retrieval | Limited tools inside a defined workflow | Write access to systems of record, money, code, or external communications |
| Autonomy | Single-step or closely supervised | Bounded multi-step execution | Extended execution with limited supervision |
| Exposure and scale | Internal, limited users | Customer-facing or operationally material | Broad external reach or critical operations |
| Reversibility | Errors are easy to detect and undo | Recovery is possible but costly | Actions may be difficult, slow, or impossible to reverse |
| Typical route | Self-service controls and automated evidence | Domain evals, owner approval, sampled monitoring | Independent challenge, explicit authorization, strict runtime limits, incident exercise |
Table 1. Illustrative production AI risk-tier matrix. This is an original synthesis, not a universal scoring standard. It is informed by Stanford’s deployment tiers and OpenAI’s discussion of task suitability, action-space constraints, and approval for consequential actions (Shavit et al., 2023, pp. 8–10; Stanford University IT).
This matrix is intentionally qualitative. A neat score can conceal judgment rather than improve it. A low-autonomy system may still be high risk if it influences medical care or employment. A highly autonomous system may be tolerable inside a sandbox with synthetic data, no external connectivity, and reliable reset. Classification should therefore record both the tier and the reasoning behind it.
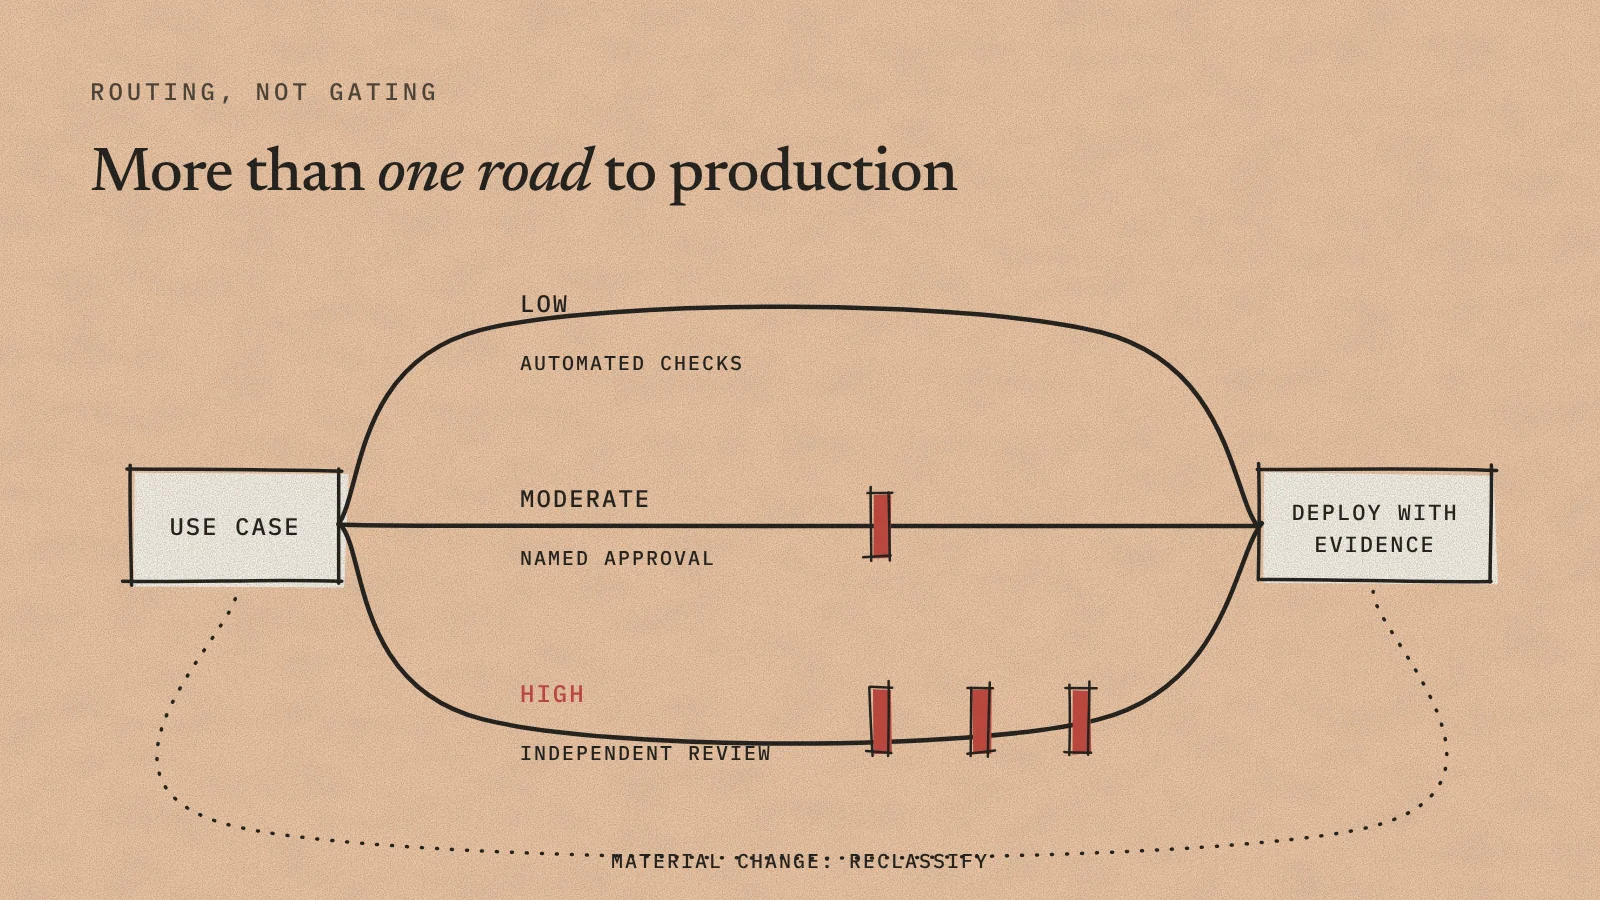
The resulting path to production should look less like a gate and more like routing:
flowchart LR
    I["<b>Describe use case</b><br/>purpose · people · data · tools"] --> C["<b>Classify risk</b><br/>impact · authority · autonomy · reversibility"]
    C --> L["<b>Low</b><br/>approved pattern<br/>automated checks"]
    C --> R["<b>Moderate</b><br/>targeted evals<br/>named approval"]
    C --> H["<b>High</b><br/>independent challenge<br/>explicit authorization"]
    L --> D["<b>Deploy with evidence</b>"]
    R --> D
    H --> D
    D --> O["<b>Observe and reassess</b><br/>behavior · changes · incidents"]
    O -->|"material change"| C

    style L stroke:#59ca6f
    style R stroke:#eead3a
    style H stroke:#ee3a48
    style D stroke:#4ea3ff,stroke-width:2px
Figure 2. A risk-routed path to production. Original synthesis based on the principle that controls and evaluations should be proportionate to capabilities, deployment context, and credible threats (Korbak et al., 2025, pp. 3–4).
Put the policy in the architecture
A policy that says an agent must act only within its authority is admirable and incomplete. The production questions are more concrete: Which identity does it use? Which tools can it call? What arguments can it pass? How much can it spend? Which action requires confirmation? How quickly can it be stopped?
OpenAI’s agent governance paper organizes operational practices around task suitability, constrained action spaces and approvals, default behavior, legibility, automatic monitoring, attributability, and interruptibility (Shavit et al., 2023, pp. 8–15). In enterprise terms, these become controls engineering teams can build and test:
- Give every agent a distinct identity and least-privilege permissions.
- Use tool allowlists, schema validation, sandboxes, network restrictions, and scoped credentials.
- Separate recommendation from execution for consequential actions.
- Set transaction, rate, time, and retry limits.
- Require approval at the point of consequence—not mechanically after every model response.
- Log model routes, prompt versions, retrieved context, tool calls, policy decisions, and release metadata.
- Maintain rollback, suspension, credential-revocation, and shutdown mechanisms.
The industry guidance is directionally consistent: permissions should match defined scope, inherited authority should be intentional, and named people should own monitoring, high-impact approval, intervention, and incident response (Palo Alto Networks, “A Complete Guide to Agentic AI Governance”). The important move is translating that advice into defaults in the platform, not another document for teams to interpret independently.
flowchart LR
    DES["<b>Design</b><br/>purpose · tier · owner"] --> BLD["<b>Build</b><br/>identity · permissions · sandbox"]
    BLD --> TST["<b>Test</b><br/>task · misuse · control evals"]
    TST --> REL["<b>Release</b><br/>evidence · approval · version"]
    REL --> OPR["<b>Operate</b><br/>logs · monitors · limits · response"]
    OPR --> CHG["<b>Change</b><br/>drift · tools · scale · reclassify"]
    CHG --> DES

    style DES stroke:#4ea3ff
    style BLD stroke:#2dc5c3
    style TST stroke:#ad7aeb
    style REL stroke:#eead3a
    style OPR stroke:#59ca6f
    style CHG stroke:#ee8d3a
Figure 3. Governance embedded in the delivery lifecycle. Original synthesis informed by Shavit et al. (2023, pp. 8–15) and Korbak et al. (2025, pp. 3–4).
Treat autonomy as a bounded privilege
The word autonomous is often too blunt to be useful. An agent may choose its intermediate steps yet remain unable to spend money, contact a customer, or write to a system of record. Another may run for only five minutes but possess powerful credentials. Governance should focus on the authority actually delegated.
A useful managerial concept is an autonomy budget: the bounded amount of discretion a system receives across action scope, permissions, time, spend, scale, and reversibility. This is a proposed operating concept, not an established academic standard. Its value is that it makes a vague decision—“Are we comfortable with this agent?”—negotiable in concrete terms.
For example, a support agent might be allowed to issue one refund below $50, only for an authenticated customer, using a dedicated billing action, with a daily aggregate cap. Anything outside that envelope becomes a recommendation for a human. If evidence shows reliable performance, the organization may widen the envelope deliberately. If incidents or material changes occur, it can narrow it without removing the entire service.
This direction also appears in policy discussions. The Center for AI Policy has proposed an “Autonomy Passport” for advanced agents capable of handling money, controlling devices, or running code, intended to record capabilities, operating boundaries, safety testing, and emergency contacts (Center for AI Policy, 2025). Whether or not that specific federal proposal is adopted, the underlying enterprise question is already present: can you state what authority an agent has, where it operates, how it was tested, and who can stop it?
Make evidence continuous—and test the controls themselves
A model inventory updated quarterly cannot tell you what ran yesterday. Production systems change through prompt edits, model substitutions, retrieval updates, new tools, permission changes, provider behavior, and shifts in user traffic. Pre-deployment assurance remains necessary, but it certifies a configuration that begins aging as soon as it ships.
Governance evidence should therefore be produced as part of delivery and operation:
| Evidence object | What it should answer | Example automated source |
|---|---|---|
| System record | What is live, for whom, and for what purpose? | Deployment and service catalog |
| Component record | Which model, prompt, data source, tool, and permission set ran? | Trace and configuration metadata |
| Evaluation record | Did the system meet task, safety, policy, and control thresholds? | CI and sampled production evals |
| Decision record | Who approved the use case or accepted residual risk, and why? | Workflow tied to a release version |
| Runtime record | What did the system actually do? | Traces, tool calls, policy events, redaction events |
| Incident record | What happened, who acted, and did the fix work? | Alert, response timeline, rollback, post-fix eval |
Table 2. A minimum continuous evidence model for production AI. Original synthesis informed by OpenAI’s emphasis on legibility, monitoring, attributability, and control (Shavit et al., 2023, pp. 11–15).
When these records share identifiers—workflow, release, model route, trace, owner, policy, and incident—a governance question becomes a query instead of a meeting. Engineering can debug from the same evidence that risk and audit use for assurance.
But observability alone is not proof of control. Monitoring can add cost, retain sensitive information, create privacy concerns, and still miss behavior its detection logic was not designed to recognize (Shavit et al., 2023, pp. 12–13). And a control that exists on an architecture diagram may fail when an agent tries an unexpected sequence of actions.
That is why teams should evaluate the controls, not just the model. Korbak and colleagues propose capability- and threat-informed control evaluations: red-team exercises in which agents attempt to subvert safeguards, producing evidence about whether monitoring, approvals, resource restrictions, or shutdown mechanisms remain adequate for the deployment (Korbak et al., 2025, pp. 1–4). For most enterprise systems, the practical version is straightforward: test attempts to exceed tool permissions, evade approval thresholds, disclose restricted data, loop around spending limits, or continue after termination.
Human oversight should sit at the point of consequence
“Human in the loop” is not a complete control description. A person can be present yet unable to understand the recommendation, detect the error, or intervene before the action occurs. Conversely, requiring manual review of every low-impact draft can create alert fatigue and teach operators to approve reflexively.
Meaningful oversight specifies:
- What a person reviews: evidence, rationale, source material, or proposed action.
- When review occurs: before an irreversible action, after a reversible low-risk action, or only after an anomaly.
- Who is qualified and authorized to decide.
- How long the reviewer has and whether the system can act while waiting.
- What happens after rejection, timeout, escalation, or system failure.
Accountability should be equally explicit. Model providers shape capabilities; deployers and integrators configure tools and workflows; business owners define purpose and accept operational outcomes; engineering maintains controls; security and risk set requirements and challenge evidence; operators respond to alerts. Autonomy changes how work is performed. It does not make the organization’s responsibility autonomous.
Reclassify when authority or consequences change
Annual review is a calendar event, not a risk signal. Reassessment should be triggered when the system materially changes.
Useful triggers include:
- adding a write-capable tool or external communication channel;
- expanding data access or permissions;
- moving from recommendation to execution;
- increasing run duration, transaction limits, user population, or geographic reach;
- substituting a model with materially different capabilities or behavior;
- changing a prompt, retrieval source, or workflow in a way that affects policy-relevant behavior;
- introducing agent-to-agent interaction;
- observing a serious incident, control failure, or sustained evaluation regression.
Not every trigger requires a committee. A policy engine can route a model substitution through regression evals, send a new read-only tool to the owner, and escalate a new payment permission to security and risk. The change determines the review—not the other way around.
Three systems, three governance postures
| Use case | Principal risk | Bounded authority | Assurance before release | Runtime governance |
|---|---|---|---|---|
| Internal knowledge assistant | Unsupported answers or inappropriate document retrieval | Read-only retrieval from approved collections | Retrieval, faithfulness, and access-control tests | Sampled quality evals; access and source logging |
| Customer refund agent | Incorrect payment or account change | Authenticated customer; refund-only tool; per-transaction and daily limits | Tool-use, edge-case, misuse, and approval-threshold tests | Every action logged; anomaly alerts; rapid suspension |
| HR screening assistant | Unfair or unlawful influence over consequential decisions | Recommendation only; no automatic disposition | Domain, bias, validity, privacy, and human-factors review | Outcome monitoring, decision records, periodic independent review |
Table 3. The model may be similar, but deployment authority and consequences determine the governance posture. Original synthesis informed by Stanford’s risk classification and OpenAI’s task-suitability and action-space practices (Shavit et al., 2023, pp. 8–10).
A practical production AI governance checklist
Before a use case takes the accelerated path, a team should be able to answer:
- Is its purpose, owner, affected population, and prohibited use documented?
- Is the risk tier based on data, decision impact, tools, permissions, autonomy, exposure, scale, and reversibility?
- Are identity, least privilege, action limits, and approval thresholds enforced technically?
- Do evaluations reflect the real task, users, misuse cases, and operating environment?
- Are releases tied to model, prompt, retrieval, tool, permission, and evaluation evidence?
- Can operators detect abnormal behavior, reconstruct an action, roll back a change, revoke authority, and stop the system?
- Are material-change triggers and incident owners defined?
- For interacting agents, have the interactions—not only the components—been tested?
If the answer is yes, governance has done something more valuable than approve a document. It has created a repeatable path to production.
How Anosys supports operational governance
Anosys is a monitoring and evidence layer, not an enforcement point. It can show what an agent did, check it against your rules, keep the record and alert the owner. Actions that must be prevented belong in the model gateway, tool broker, identity layer or application. An alert after an unauthorized payment is not a substitute for denying the call. With that boundary, here is how the pieces above map to the product:
- Runtime record. Traces from the agent SDKs and OpenTelemetry record model routes, tool calls, handoffs, tokens and errors, with your own fields for workflow, owner, release and risk tier.
- Evaluation record. Evaluations score live traffic and datasets with versioned rubrics, compare a candidate release against the current one, and measure how well each judge agrees with human reviewers. Sample rates can follow the risk tier: dense for new releases and high-risk workflows, light for the rest.
- Policy checks. The Alert Builder runs deterministic rules (for example, a tool outside a workflow's approved list, or email addresses and card numbers in prompts or responses) and AI-evaluated rules written in plain language, and sends matches to Slack, email or a webhook such as your incident tool.
- Repeatable checks. Pipelines run those checks, evaluation runs and reports on a schedule, with a run history of what was checked and when.
- Data controls. Redaction and encryption with your own key limit what reaches Anosys and who can read it. See Security and data controls.
Together these support the loop described above: tag each workflow with its owner and tier, record what it does, score it in proportion to its risk, route exceptions to the owner, and feed incidents and material changes back into classification.
Talk to us
Build an evidence trail for your AI workflows
Record what each agent did, score it in proportion to its risk, and route exceptions to the owner. Start on the free plan, or walk through your setup with us.
Frequently asked questions
What is AI governance in production?
AI governance in production is the combination of decision rights, technical controls, continuous evidence, and operational processes used to keep a deployed AI use case within its approved purpose and risk limits throughout its lifecycle.
Does AI governance slow product development?
It can when every use case follows the same manual review. A risk-tiered model can accelerate lower-risk work through approved components and automated evidence while reserving deeper review for high-impact or highly autonomous systems.
How should an organization classify AI risk?
Classify the deployed use case across data sensitivity, decision impact, tools and permissions, autonomy, external exposure, scale, reversibility, and consequences of failure. Reclassify it when those characteristics materially change (Stanford University IT).
When is human approval necessary for an AI agent?
Human approval is most valuable before consequential or difficult-to-reverse actions and when the reviewer has the information, competence, time, and authority to intervene. It should not be added mechanically to every low-risk interaction (Shavit et al., 2023, pp. 9–10).
What evidence should an AI governance program collect?
At minimum, collect the live system and owner, model and prompt versions, data and tool access, evaluation results, policy and redaction events, approvals, runtime actions, changes, incidents, and remediation evidence.
Explore the AI Governance and Compliance solution and Security and data controls.
References
- Center for AI Policy. “AI Agents: Governing Autonomy in the Digital Age.” May 22, 2025.
- Hammond, Lewis, et al. “Multi-Agent Risks from Advanced AI.” Cooperative AI Technical Report 1, February 2025.
- Korbak, Tomek, Mikita Balesni, Buck Shlegeris, and Geoffrey Irving. “How to Evaluate Control Measures for LLM Agents? A Trajectory from Today to Superintelligence.” April 2025.
- Palo Alto Networks. “A Complete Guide to Agentic AI Governance.”
- Shavit, Yonadav, et al. “Practices for Governing Agentic AI Systems.” OpenAI, December 2023.
- Stanford University IT. “Know Your Risks: Agentic AI Risk Classifications.”

