How to Reduce LLM Costs: Find Where the Tokens Go First
Most LLM cost work starts with a guess: switch to a cheaper model, shorten the system prompt, cap the response length. Some of those help. Without per-step token data, though, you can't tell which one matters for your workload, and you can't tell whether the change hurt answer quality.
This post walks through where tokens go in a typical multi-turn agent, the changes that usually have the largest effect, and what to measure before and after each one.
A worked example: one six-turn conversation
Take a booking assistant that answers each user message with one model call and one tool call. The assumptions:
| Part | Tokens |
|---|---|
| System prompt and tool definitions | 2,500, sent on every call |
| User message | 150 per turn |
| Tool result (search results, JSON) | 800 per turn |
| Assistant response | 300 per turn |
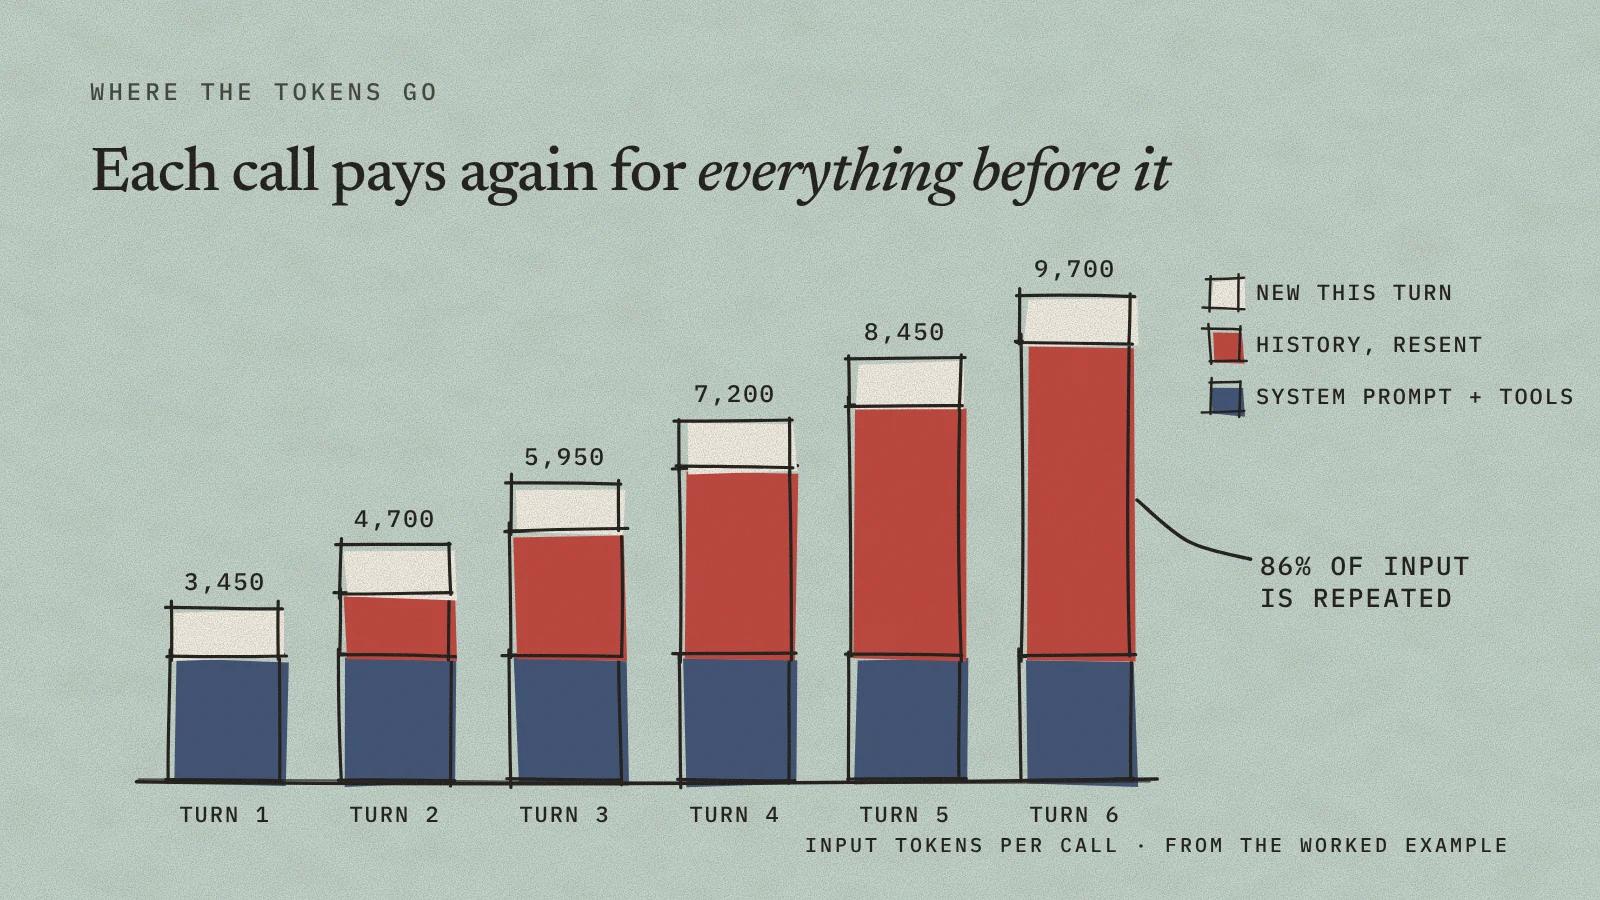
Because chat APIs are stateless, every call resends the system prompt and the whole conversation so far. Over six turns, input tokens add up like this:
| Turn | Static prefix | History from earlier turns | New this turn | Input total |
|---|---|---|---|---|
| 1 | 2,500 | 0 | 950 | 3,450 |
| 2 | 2,500 | 1,250 | 950 | 4,700 |
| 3 | 2,500 | 2,500 | 950 | 5,950 |
| 4 | 2,500 | 3,750 | 950 | 7,200 |
| 5 | 2,500 | 5,000 | 950 | 8,450 |
| 6 | 2,500 | 6,250 | 950 | 9,700 |
| Total | 15,000 (38%) | 18,750 (48%) | 5,700 (14%) | 39,450 |
Output is only 1,800 tokens. At an assumed $3 per million input tokens and $15 per million output tokens, the conversation costs about $0.15, and roughly 80% of that is input.
Two things stand out:
- 86% of input tokens are repeats. The model has already seen the prefix and the history; you pay for them again on every turn.
- Tool results dominate the history. 800 of the 1,250 tokens added per turn are search results the user never reads, carried forward for the rest of the conversation.
Your numbers will differ. The shape usually doesn't, and you can only see it if each call records input, output and cached tokens separately.
Five changes that usually matter most
1. Turn on prompt caching and keep the prefix stable
Most providers bill cached input tokens at a fraction of the normal price. Caching only works if the start of the prompt is byte-for-byte identical between calls, so put static content first (instructions, tool definitions, examples) and anything that changes (timestamps, user names, retrieved documents) after it.
Measure: cached input tokens as a share of all input tokens, per workflow. If it stays near zero after you enable caching, something early in the prompt is changing on every call.
2. Shrink tool results before they enter the history
Keep the full tool result for the turn that needs it, then replace it in the history with a short summary or the few fields the agent will refer to later. In the example, cutting each stored tool result from 800 to 200 tokens reduces the history column from 18,750 to 9,750 tokens.
Measure: tokens per tool result by tool name. One verbose tool is often most of the problem.
3. Bound the history
For long conversations, summarize older turns or keep only the last N. Test this on real long conversations, because a summary that drops one detail (a date, an order number) can cause a wrong answer several turns later.
Measure: cost per conversation by number of turns, and eval scores for conversations longer than your cut-off, before and after.
4. Route steps, not whole conversations, to smaller models
Classification, extraction, short rewrites and routing decisions rarely need the largest model. Planning and the final answer often do. Routing by step is safer than routing by conversation.
Measure: cost and eval score per step and model. A cheaper model that needs more retries can cost more in total.
5. Stop retry loops
An agent that retries a failing tool and resends the full context each time is the most common cause of sudden cost spikes. Add a retry limit per tool and an overall token or step budget per run, and return a clear fallback when it's reached.
Measure: runs with more than N calls to the same tool, and the share of total spend they account for. Alert on it.
Watch quality while you cut
Every change above can lower quality in ways a cost chart won't show. Before shipping a cost change:
- Pick a sample of real conversations, including long ones and ones with tool errors.
- Score the current version with the rubric you already use for quality.
- Run the cheaper version on the same inputs and score it again.
- Ship only if the score holds, then watch the live score for a week.
What to record on every call
To do any of this you need, per model call: model, input tokens, cached input tokens, output tokens (and reasoning tokens if the model reports them), latency, the workflow or agent name, the prompt version, and a conversation ID. Per tool call: tool name, result size and status. Most agent SDKs and OpenTelemetry GenAI instrumentation emit most of these; the workflow name and prompt version are usually up to you.
Doing this with Anosys
The OpenAI and Anthropic SDKs and OpenTelemetry send tokens (including cached and reasoning tokens), latency and tool calls for every span. In the console you can:
- chart cost per conversation, workflow or model, and see how it grows with conversation length
- open the trace of an expensive run to see which step and which tool result made it expensive
- score the cheaper version against the current one with Evaluations
- set an alert on cost per run or on runs with repeated tool calls
For coding tools such as Claude Code and Codex, see Track AI and coding spend.
Free plan, no credit card
Find where your tokens go, for free
Record cost on every call and see which models, prompts and workflows drive spend, before you start optimizing.

