Continuous Evals for Production AI Systems
Someone forwards a screenshot of a bad answer and asks, "Is this normal?" Often nobody can say. The eval suite passed before launch and nothing has been measured since, while the model version, prompts, retrieval index, tool schemas and users have all changed.
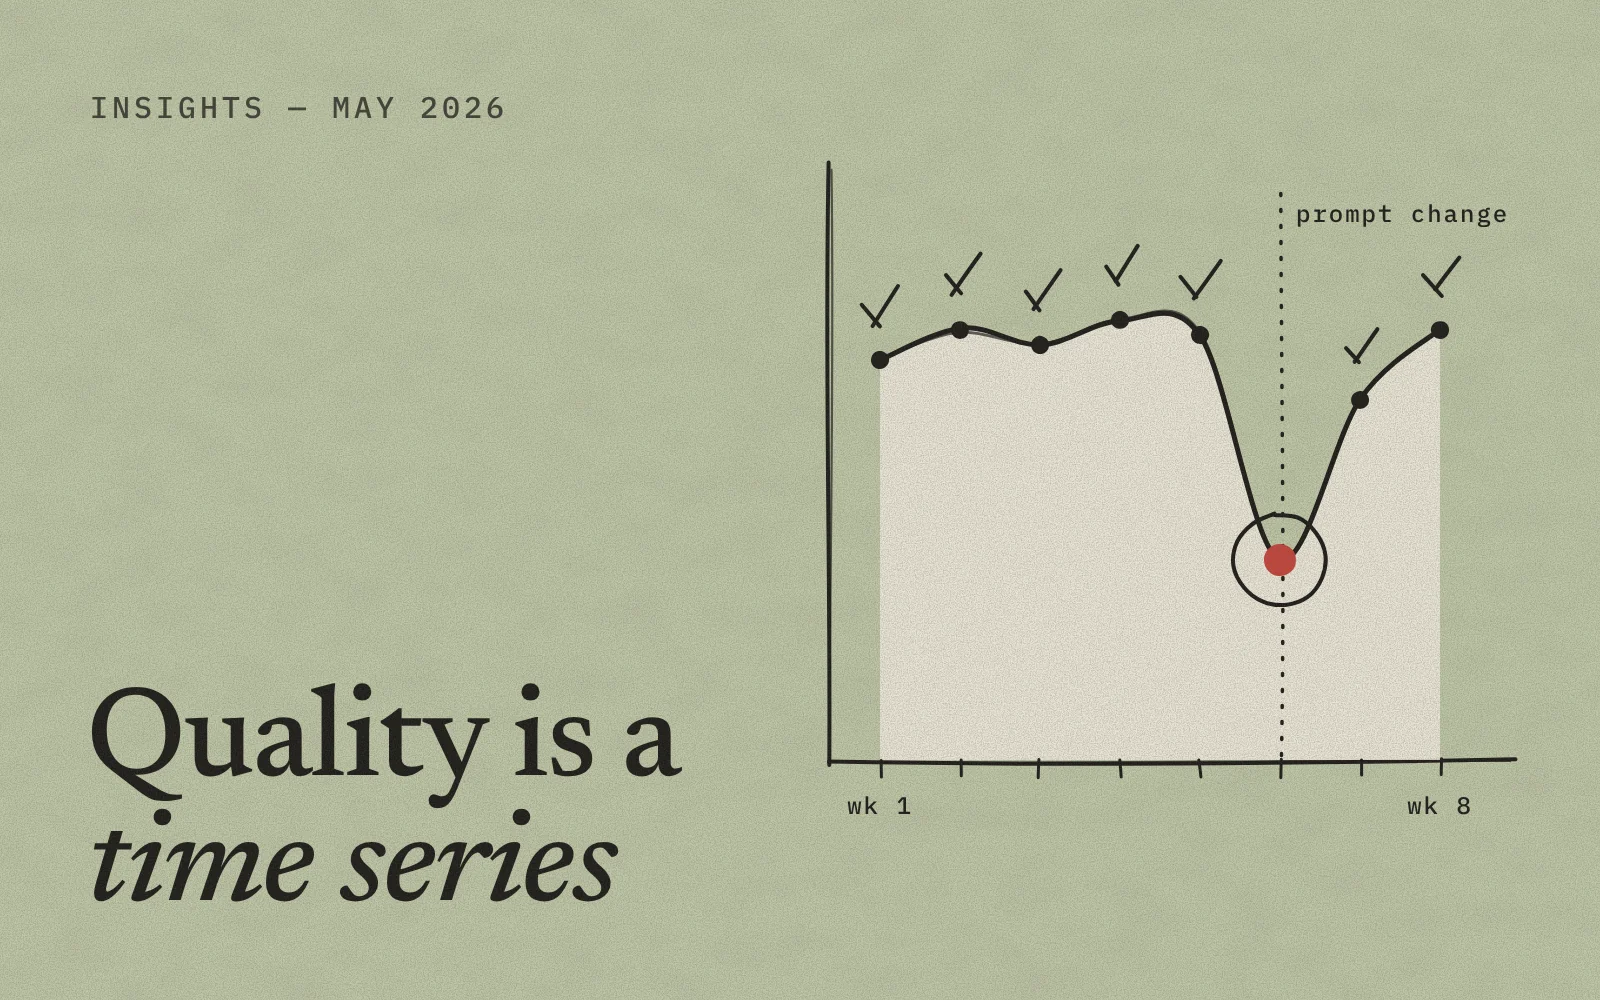
Pre-launch evals describe a version of the system that stops existing soon after it ships. Production quality is a time series, and if you don't measure it continuously, your quality signal is whichever screenshot reaches a manager first.
Why these regressions are easy to miss
Latency, error rates and availability stay normal while the system gives answers that are plausible but wrong, slightly less helpful than last week, based on misread tool results, or out of policy. A small prompt edit can lower task completion with no errors at all. A provider-side model update can change refusal behavior in a system you didn't touch.
What you measure matters as much as how often:
| Dimension | What it catches | Typical owner |
|---|---|---|
| Task success | Whether the workflow did the job it exists for | Product, AI engineering |
| Faithfulness | Whether the answer is supported by the retrieved or tool-provided evidence | ML engineering |
| Safety and policy | Harmful content, refusals, regulated statements, brand rules | Governance, trust |
| Tool correctness | Wrong tool, wrong parameters, stale output, retry behavior | Engineering |
| Cost and quality | Quality held up only by more tokens or larger models | Product, finance |
| User outcome | Abandonment, escalation, conversion, follow-up questions | Product, operations |
A system can improve on one of these and get worse on another, which is why one quality number isn't enough.
Watch for divergence, not just drops
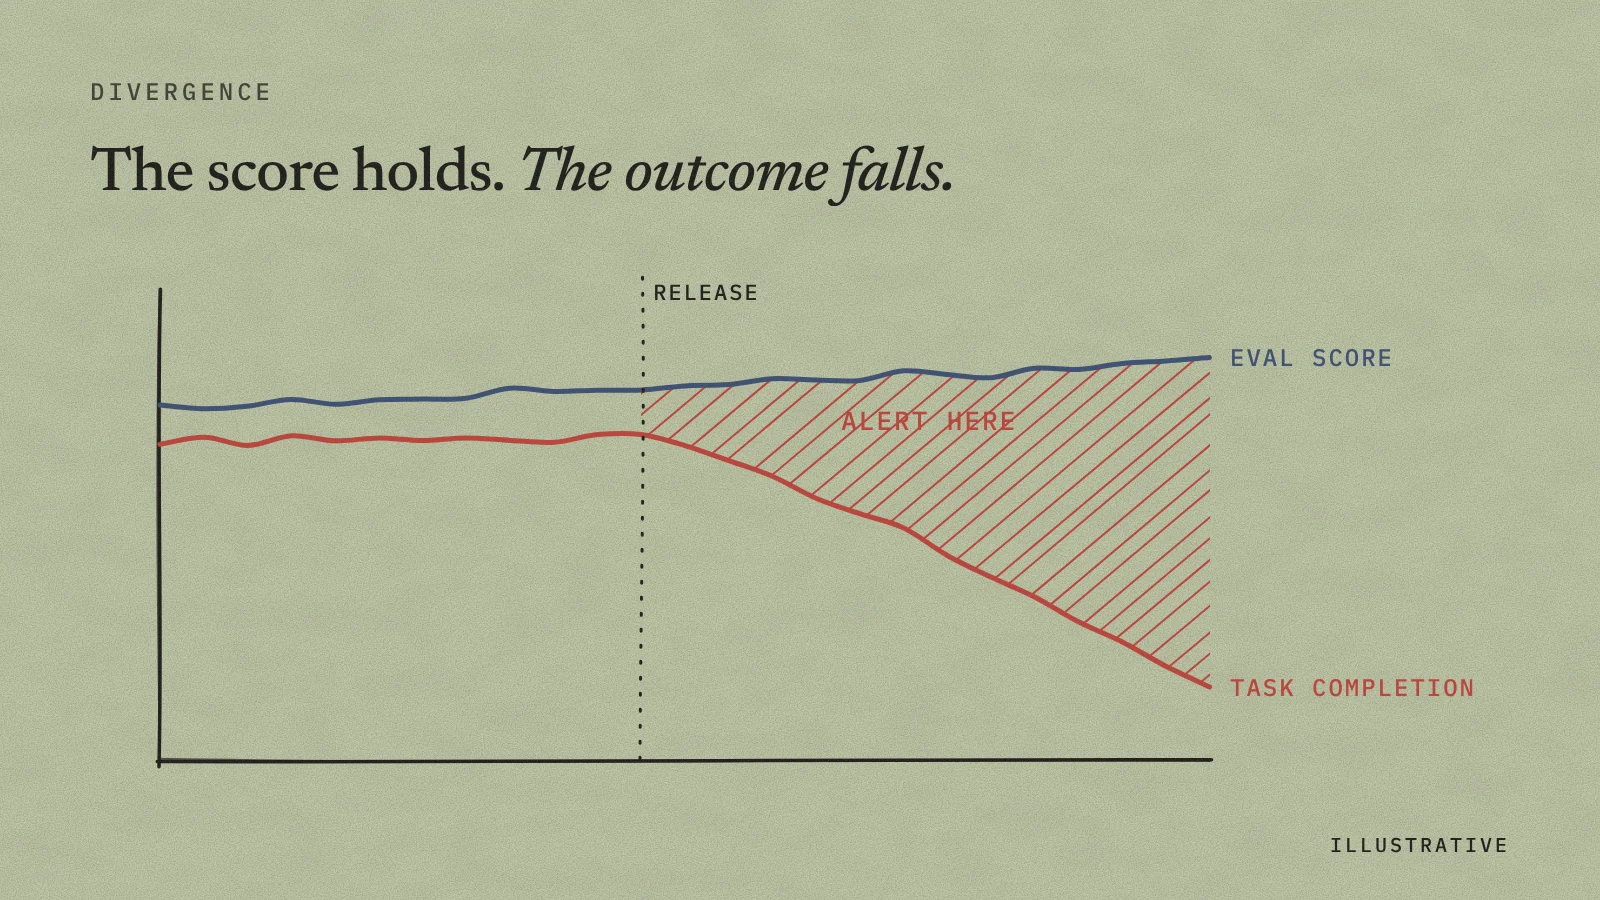
A score on its own says little. What it moves with says more. Four patterns worth alerting on:
- The score rises while task completion falls. The model got better at sounding right, and the eval measures the sound.
- Relevance holds while tokens per run double. Quality is being kept up with more context.
- Safety passes while escalations climb. The answers are compliant and unhelpful.
- A new model is faster but misses policy more often. That is a tradeoff someone should approve, not discover in an audit.
flowchart LR
    CI["<b>CI evals</b><br/>known cases,<br/>every prompt change"] --> ATT
    PROD["<b>Production evals</b><br/>sampled live traffic"] --> ATT["scores attached to traces,<br/>cost, releases, users, outcomes"]
    ATT --> AGREE["scores and outcomes agree<br/><i>keep shipping</i>"]
    ATT --> DIV["<b>divergence</b><br/>score fine · outcomes falling<br/><i>alert and decide</i>"]
    style CI stroke:#4ea3ff,stroke-width:2px
    style PROD stroke:#2dc5c3,stroke-width:2px
    style DIV stroke:#ee3a48,stroke-width:2px
    style AGREE stroke:#59ca6f
All four need the score on the same timeline as traces, cost, user behavior and business outcomes.
Build the program in five steps
- Write rubrics for your own rules. Generic benchmarks don't know your refund policy or tone of voice. Start with three or four rubrics that match the dimensions above for your most important workflow.
- Keep three datasets. A golden set with trusted answers, a regression set of cases that broke before, and a red-team set of adversarial inputs. Add a case to the regression set every time an incident is fixed.
- Run in CI on every prompt, model or retrieval change, against those datasets.
- Run on production samples on a schedule (see sampling below), with each result attached to the trace it scored.
- Treat a regression as a decision: roll back, reroute, fix the prompt, or accept the tradeoff and write down why.
Check the judges
Model-graded evals are only as good as the judge. Before you trust a score:
- Have people label 50 to 100 real outputs with the same rubric.
- Measure how often the judge agrees with them. If agreement is low, fix the rubric before you look at trends.
- Re-check after changing the judge model or rubric. A score change caused by a new judge looks exactly like a change in your system.
- Version rubrics, so results from different weeks are comparable.
Sample production sensibly
You don't need to score every interaction with every judge. A tiered pattern works for most teams:
- High-risk workflows: a higher sample rate.
- New releases: heavy sampling for the first hours or days.
- Everything else: a small continuous sample.
- Always: incidents, negative user feedback and runs that hit an alert.
Judges cost tokens too, so give eval runs their own cost attribution.
Evals also copy production data into another system. Apply the same redaction and retention rules to eval inputs and results as to the traces they came from.
Doing this with Anosys
In Anosys, Evaluations holds versioned templates (model judges and rules), datasets (golden, regression, red team, calibration), Eval Runs that score live traces on a schedule or backfill a past range, Experiments that compare two variants on the same dataset, and Review & Calibration, where people label samples and you see how often each judge agrees with them.
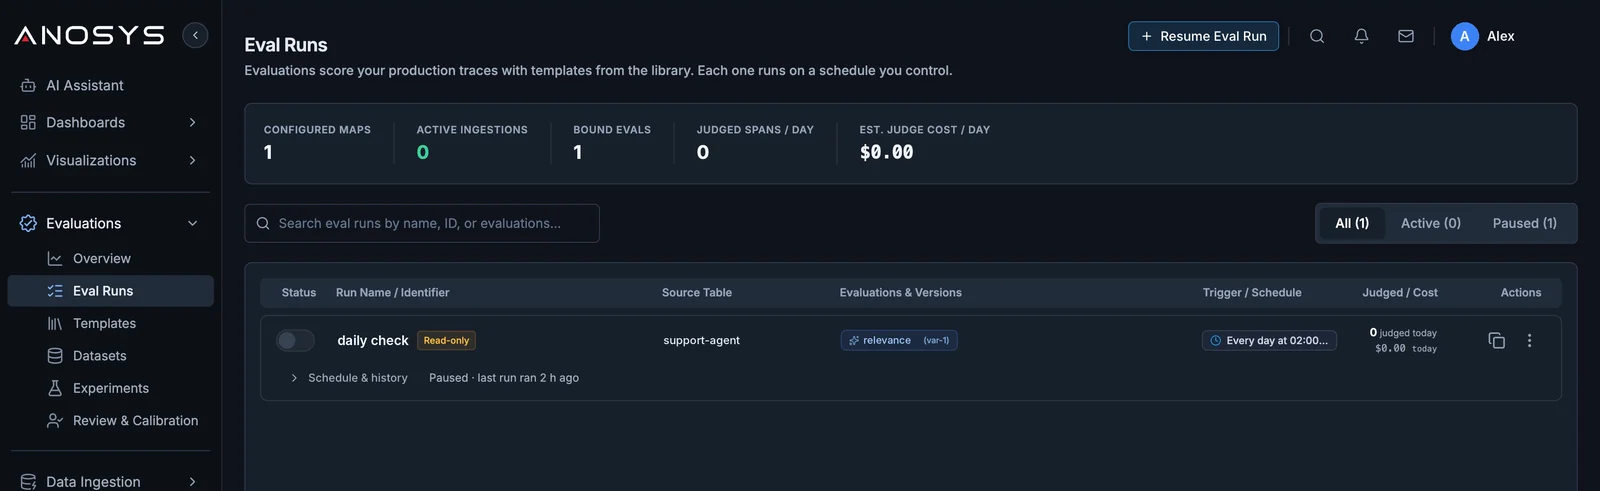
Because results are stored with the traces they scored, a dashboard can put eval scores next to cost, release and user outcome, and the Alert Builder can fire on a score drop. To run evals on a schedule together with other steps, add them to a pipeline.
Explore the AI Quality and Evals solution.
Free plan, no credit card
Run evals on production traffic for free
Score live traces with your own rubrics, compare releases, and get alerted when quality drops, with every score linked to the run it came from.

