Evaluations on live traffic
Up is not the same as good
A model can stay fast and available while answers get less relevant or less safe. Uptime checks will not tell you.
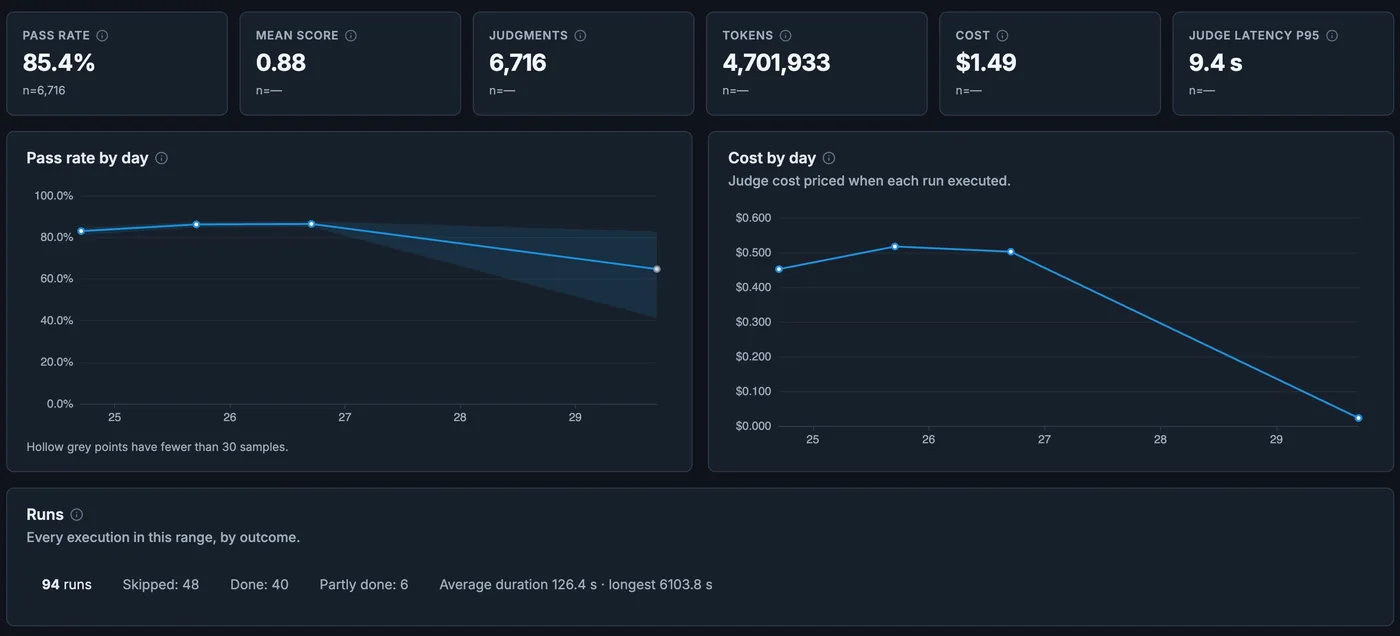
Scores linked to the run
Each eval score is attached to the trace it judged, so a drop in relevance leads straight to the prompts, model versions and users involved.
Pick or write a judge, run it on live traces or a dataset, compare against human review, and alert on regressions.
Score
Run quality, safety, relevance, policy, latency, cost, and custom evals by workflow.
Compare
Track behavior across prompts, models, releases, cohorts, customers, and provider changes.
Diagnose
Link regressions to traces, tool calls, model settings, data changes, and affected user segments.
Gate
Use eval evidence to trigger alerts, release reviews, owner handoffs, and remediation workflows.
What teams can do
- Track quality, safety, relevance, and policy scores in CI and production
- Compare task success, groundedness, safety, relevance, refusals, and cost over time
- Alert when production evals, latency, refusals, error rates, or engagement drift from expected ranges
- Connect eval failures to traces, prompts, tools, releases, and business KPIs
Can Anosys monitor multiple model providers?
Yes. Anosys supports OpenAI, Anthropic, Claude Code, custom LLM integrations, and OpenTelemetry-based instrumentation.
Can evals run in production?
Yes. Anosys supports production monitoring and continuous evaluation so regressions are detected after deployment, not only in test suites.