Evaluations
Evaluations score what your AI actually produced: is the answer relevant, correct, safe, on-policy? Errors and latency can't tell you that.
Everything lives under Evaluations in the console:
| Page | What it's for |
|---|---|
| Overview | Scores over time across all your evaluations |
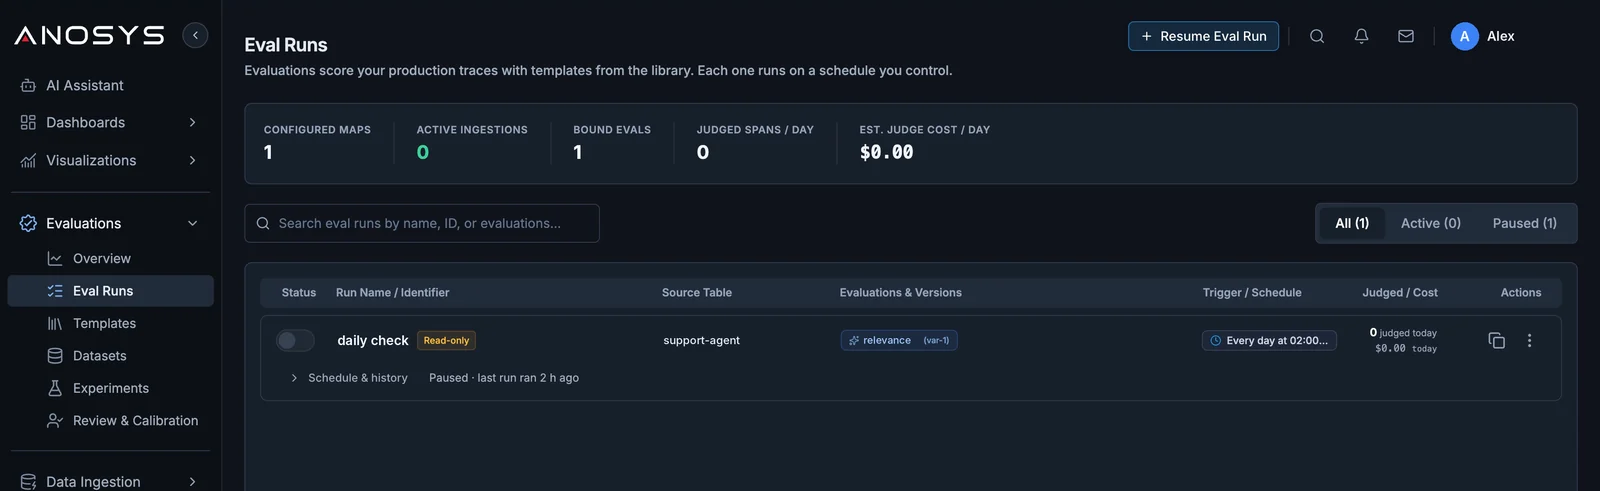
| Eval Runs | Score live traces on a schedule, or backfill past data |
| Templates | The library of evaluations (judges and rules) you can use and version |
| Datasets | Fixed sets of test cases: golden answers, past regressions, red-team prompts |
| Experiments | Compare two variants (for example two prompts or models) on the same dataset, or read out an A/B test |
| Review & Calibration | People label samples, and you see how well each judge agrees with them |
%%{init: {"flowchart": {"curve": "linear"}}}%%
graph LR
    T["Templates"] --> R["Eval Runs<br/>on live traces"]
    T --> E["Experiments<br/>on datasets"]
    D["Datasets"] --> E
    R --> O["Overview"]
    R --> V["Review & Calibration"]
    V -->|"improve the judge"| T
    R -->|"low scores"| A["Alert Builder"]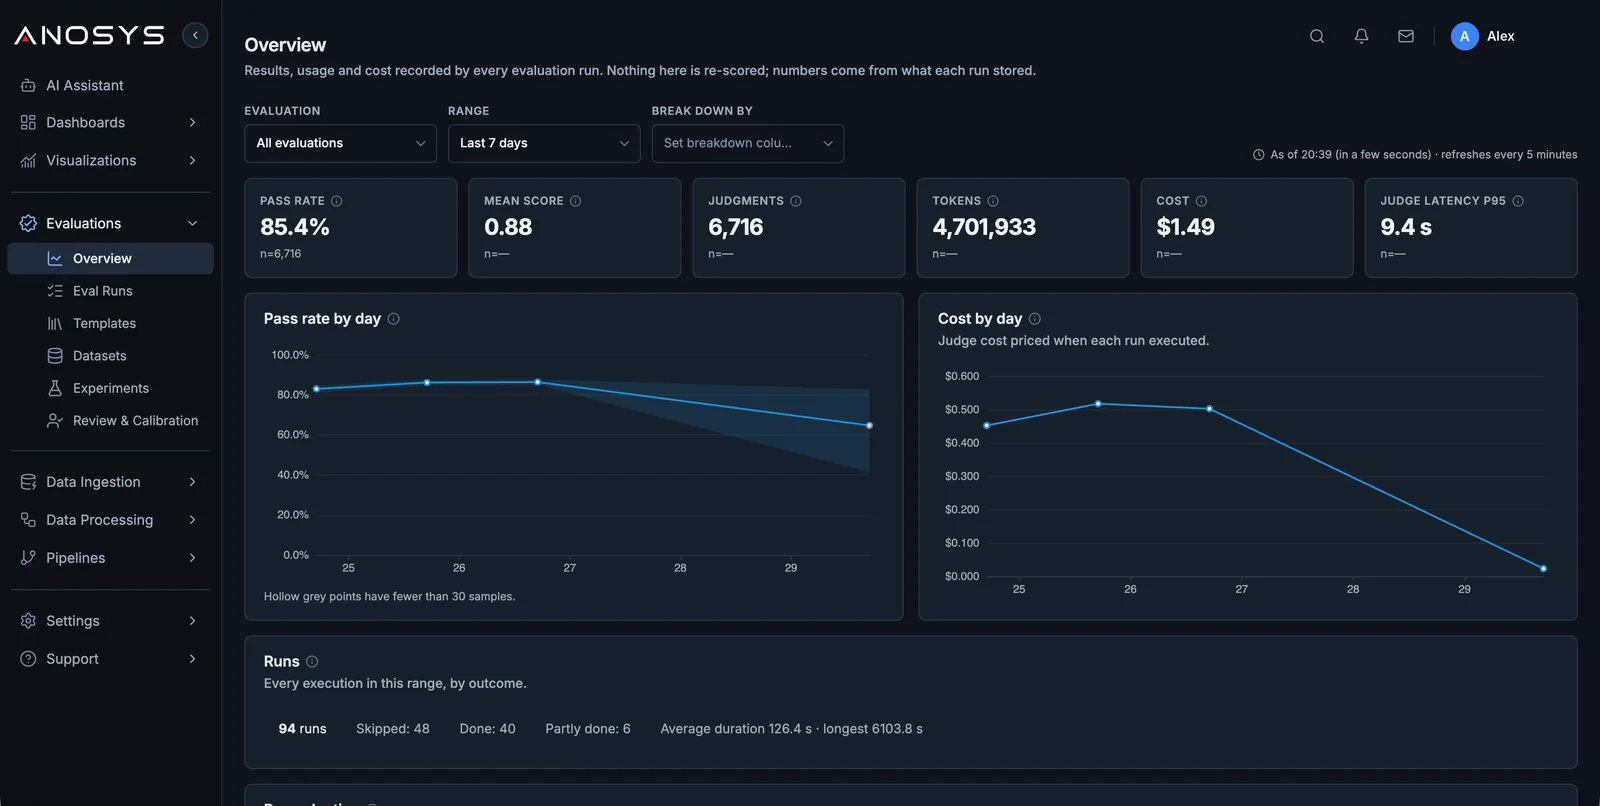
Score live traffic with an Eval Run
- Go to Evaluations → Eval Runs and start a new run.
- Follow the wizard:
- Source & Spans: pick the endpoint and the spans to score (for example, final answers).
- Pick Evals: choose one or more templates.
- Variable Mapping: tell each template where its inputs are, such as the user's question and the model's answer.
- Sample Validation: try it on a few real samples first and read the scores.
- Judge & Triggers: choose the judge and what happens on low scores.
- Pipeline & Review: set the schedule and send a share of results to human review.
- Save. New traffic is scored on schedule. Use backfill to score a past time range.
Validate before you schedule
Sample Validation is the cheapest place to catch a wrong mapping. If scores look random, check Variable Mapping first.
Templates
Evaluations → Templates holds the evaluations you can run. A template is either a judge (a model that scores against a rubric) or a rule (for example must include, must not include or matches pattern). Templates are versioned: published versions don't change, so results stay comparable over time.
Datasets
Evaluations → Datasets stores test cases you run again and again. Common kinds:
| Kind | Use it for |
|---|---|
| Golden | Curated examples with trusted answers, the main test set |
| Regression | Cases that broke before, so they stay fixed |
| Red team | Adversarial inputs such as prompt injection or unsafe requests |
| Calibration | Outputs with human labels, to check how well a judge agrees with people |
Add rows by uploading a file, by hand, or straight from traces (including failed ones). Split rows into dev, test and holdout sets.
Experiments
Evaluations → Experiments answers "is B better than A?":
- Offline comparison runs two variants on the same dataset version and compares them example by example.
- A/B readout analyses an A/B test you already ran in production, from your own logs.
Each experiment ends with a decision you record: Ship, Iterate or Stop.
Review & Calibration
Judges can be wrong. Evaluations → Review & Calibration sends samples to people, who mark them pass, partial or fail with a reason. Anosys then shows how often each judge agrees with your reviewers, so you know which scores to trust and where to improve the rubric.
Next steps
- Monitor agents in production: alerts on low scores
- Pipelines: run evaluations as part of a scheduled job

