Catch quality regressions early
ML engineers, PMs and QA
Quality drifts after prompt edits, model swaps, data updates and new user patterns. Uptime checks do not say whether answers are still useful.
Scores with the trace attached
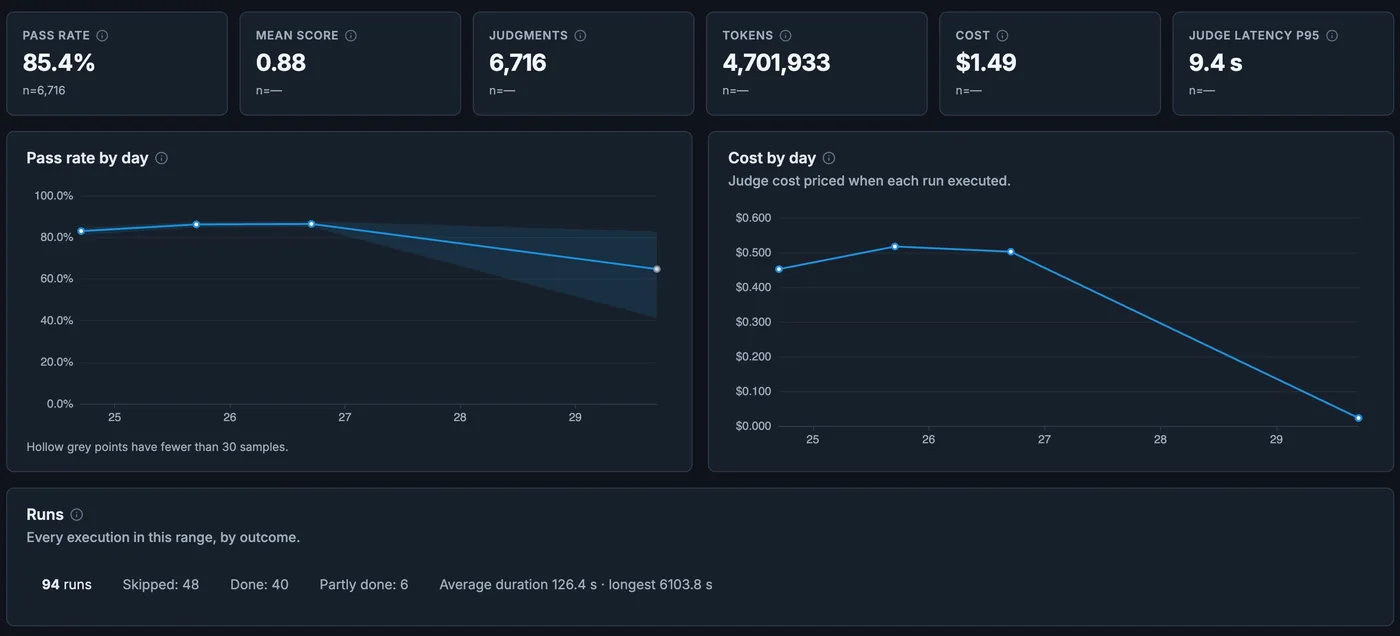
Judges score outputs continuously, and each score links to its trace, so a drop leads to the prompts, versions and users involved.
Pick judges, run them where behavior changes, and follow regressions to their traces.
Score
Run quality, safety, relevance, policy, and custom evals in CI and production.
Monitor
Track output quality, latency, refusals, error rates, cost, and user impact after deploys.
Compare
Compare versions, prompts, models, segments, workflows, and release cohorts.
Gate
Route regressions to owners and use eval evidence to guide release decisions.
What supports it
What you get
- Reduce regressions from prompt, model, or workflow changes.
- Give product and ML teams evidence for quality and safety decisions.
- Protect customer trust by monitoring whether AI remains useful in production.
Can Anosys run production evals?
Yes. Anosys supports continuous production evals and AutoJudge-style scoring connected to traces and operational context.
Can product managers use the eval data?
Yes. Dashboards and reports can translate evals into product quality, customer experience, and business KPI context.