How to Debug AI Agent Failures in Production
Many agent bugs never throw an exception. The service is up, the model answers every call, and the dashboards are green while the agent stops doing its job. Often the first alert is a message from product: "Is the checkout agent okay? Conversion looks soft."
Searching logs is the wrong tool for this, because agent failures are usually decisions, not exceptions: a wrong path, a tool called with the wrong parameters, a retry loop that eventually succeeds, a handoff that adds forty seconds and drops context. Each step is valid on its own. The run as a whole is broken.
So the unit of debugging changes. For a service you debug a request. For an agent you debug a run (every prompt, model call, tool call, handoff and retry) and compare it with three baselines: what this workflow normally looks like, what it normally costs, and what it normally achieves.
Six steps from symptom to owner
flowchart TD
    A["<b>1 · Trace the full run</b><br/>prompts · tools · handoffs · retries"] --> B["<b>2 · Compare with a baseline</b><br/>span count · tokens · tool mix"]
    B --> C["<b>3 · Check the evals</b><br/>a constraint, not proof of health"]
    C --> D["<b>4 · Check what changed around it</b><br/>releases · infra · upstream APIs"]
    D --> E["<b>5 · Measure user impact</b><br/>abandon · escalate · convert"]
    E --> F["<b>6 · Route to the owner</b><br/>of the failing step, evidence attached"]
    style A stroke:#4ea3ff,stroke-width:2px
    style D stroke:#f4ae30,stroke-width:2px
    style F stroke:#59ca6f,stroke-width:2px
1. Trace the full run
Open the whole run, not just the failing model call. The visible symptom (a slow or wrong answer) is usually several steps after the cause. Look at the shape before the content: how many steps, which tools, how many retries, where the time and tokens went.
2. Compare with a baseline
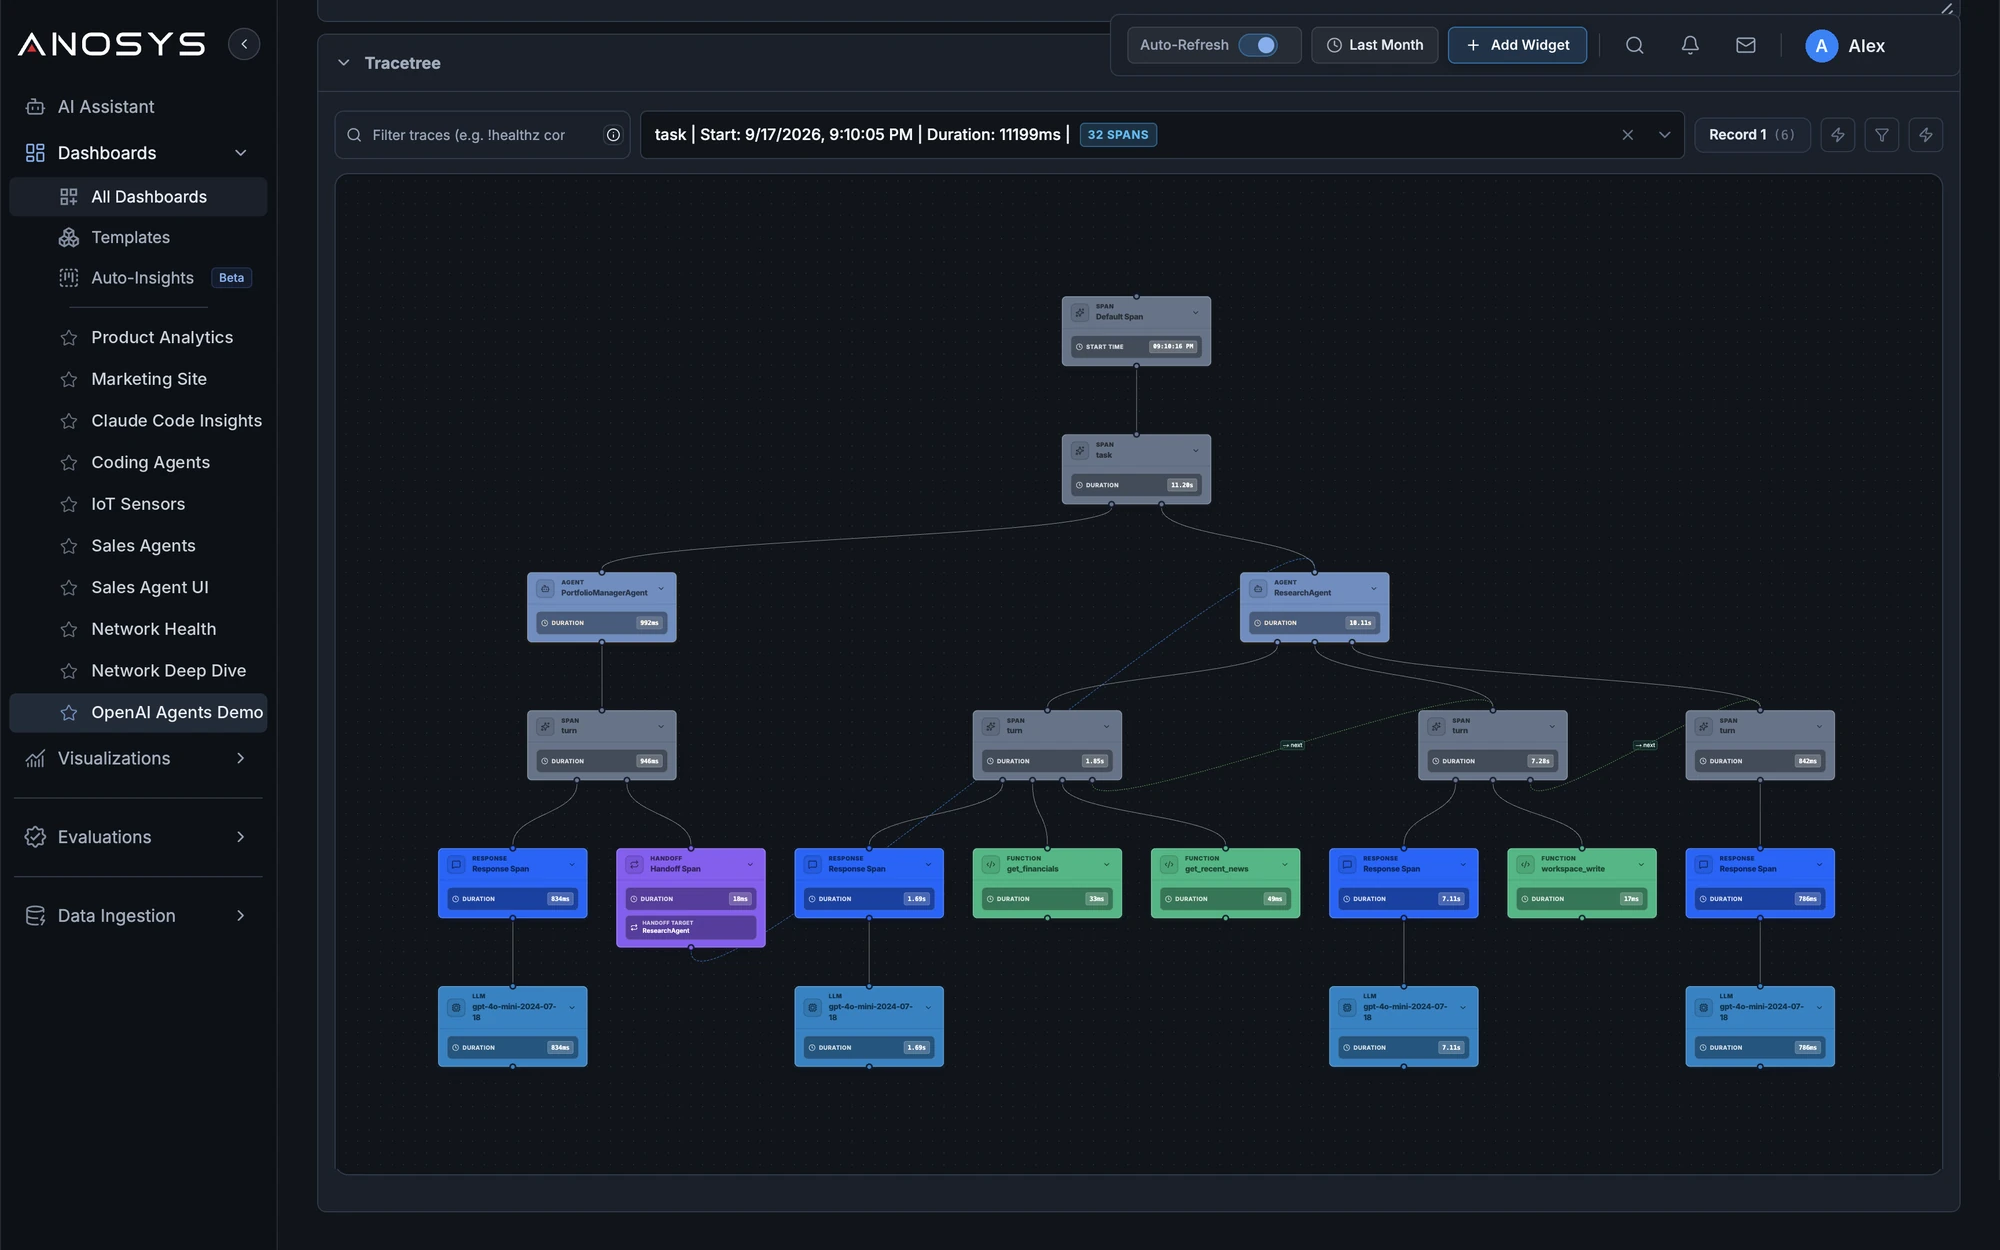
One trace rarely tells you whether something is wrong. A comparison almost always does. If yesterday's checkout runs averaged six spans and 4,000 tokens and today's average eleven spans and 13,000 tokens, the five extra spans have names, and they tell you where to look.
3. Check the evals, but don't stop there
Quality scores catch regressions that latency and error rates can't. But an eval that scores answer quality will pass a run whose problem is cost, latency or a downstream outcome. Use passing evals to rule out hypotheses, not to declare the agent healthy.
4. Check what changed around the agent
Put the run on the same timeline as releases, prompt versions, tool and API changes, retrieval index updates, infrastructure metrics and provider status. A changed API response, a backed-up queue, a feature flag that changed retrieval, or a provider model update are common causes, and none of them is in the model.
5. Measure impact in user terms
Before setting severity, find out whether affected sessions were abandoned, retried, escalated or converted less. That separates an interesting anomaly from a revenue incident, and decides whether the fix ships today or this sprint.
6. Route to the owner of the failing step
An agent run crosses team boundaries: model, tools, infrastructure, product. The incident belongs with whoever controls the step that broke, with the evidence attached, not with whoever is on call for the agent.
A finished investigation fits in two sentences, for example: Checkout-agent latency rose because inventory search started retrying after Thursday's API schema change. Affected sessions used about three times the tokens and escalated to support more often; the inventory API team owns the fix.
Runbook checklist
| Step | Question | What to inspect |
|---|---|---|
| 1 | Did the shape of the run change? | Span count, tool mix, handoffs, retries, duration, tokens |
| 2 | Did the inputs change? | User segment, account, region, task type, traffic source |
| 3 | Did a dependency change? | Releases, prompt versions, tool schemas, retrieval index, provider model versions |
| 4 | Did quality actually drop? | Eval scores, user feedback, task success, policy checks |
| 5 | Did it matter? | Abandonment, escalation, conversion, SLA breaches, cost per outcome |
| 6 | Who can fix it? | Owner of the failing workflow, service, tool or model route |
The habit that saves the most time: don't start with the model. Many agent failures come from tools, context assembly, retrieval, queues, permissions or business-rule changes. Start with the run shape and the timeline, and move to the model only when the evidence points there.
Alerts to create first
Start with alerts that combine behavior and impact:
- eval score drops after a release
- tool or API error rate increases
- runs with more than N calls to the same tool
- cost per run above a threshold
- latency high enough to reduce completion
Model routing changes and escalations are useful during an investigation but rarely worth an alert on their own.
Setting this up with Anosys
Initialize the Anosys logger for your framework once, at startup. For the OpenAI SDK:
There are equivalents for the OpenAI Agents SDK, the Anthropic SDK and the Claude Agent SDK, in Python and JavaScript, and any OpenTelemetry source works too. Pass the user and session with get_user_context so you can filter runs by who was affected. See Debug AI agents for each framework.
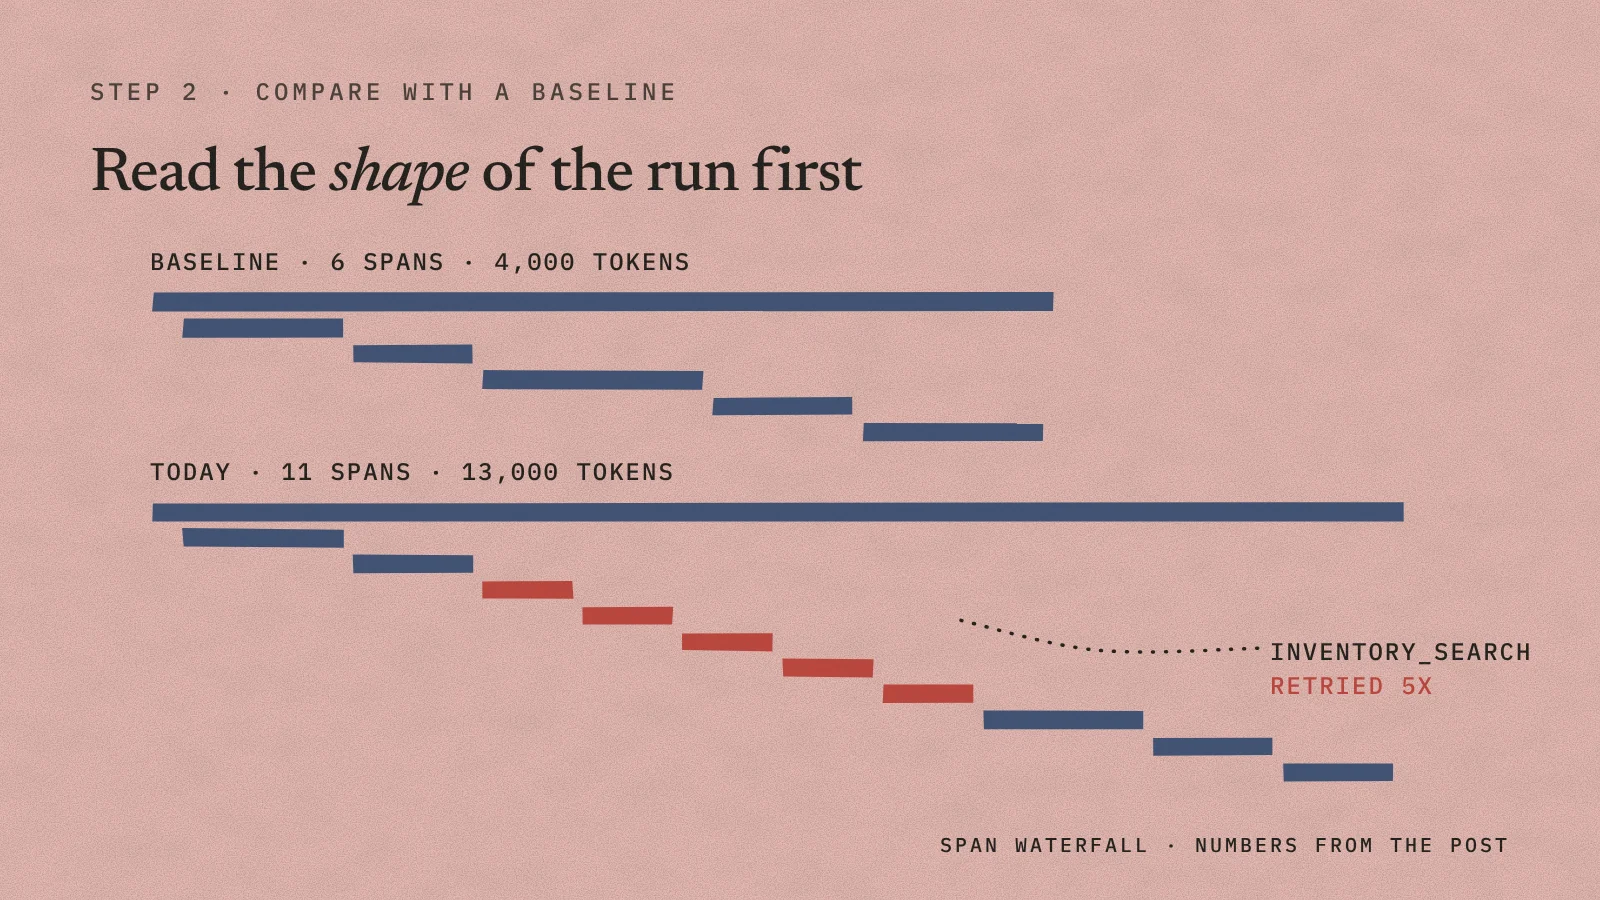
In the console, the Trace Tree and Trace Timeline cover step 1; dashboards filtered by release or date cover steps 2 and 4; Evaluations cover step 3; your own events cover step 5; and the Alert Builder sends alerts to Slack, email or a webhook. The AI Assistant can summarize the evidence for the incident channel.
Related reading: Why AI observability is not enough for production agents.
Free plan, no credit card
Debug your agents with full traces for free
See every model call, tool call, retry and handoff in one trace tree, and get alerted when a run fails or quality slips.

