What Is AI Observability? A Working Definition for Production Teams
A support assistant has been live for a month. Infrastructure dashboards are green, last week's eval scores look fine, and yet the support team says customers are asking the same question twice and giving up. Nobody can say whether the cause is the model, a tool the agent calls, the retrieval index, or something in the app around it.
That question, "why did this experience go wrong, and for whom?", is what AI observability is for. This post gives a working definition, the minimum data you need to answer it, and a way to start without instrumenting everything at once.
A working definition
AI observability is the ability to explain the behavior of an AI feature in production from the data it emits: what it did, why it did it, what it cost, and how it affected the people using it.
Two things separate it from model monitoring:
- It works on runs, not just metrics. Model monitoring tells you a score moved. Observability lets you open the runs behind the score and see the prompt, the retrieved context, each tool call and its result.
- It crosses layers. Most real failures start in one place and show up in another. A slow vector search looks like a slow model. A tool that returns an empty list looks like a hallucination.
The four layers
| Layer | What you need to see | Typical source |
|---|---|---|
| User | Sessions, clicks, retries, abandonment, feedback | Website or product tracker, app events |
| AI and agents | Prompts and responses, tool calls, handoffs, tokens, latency per step, eval scores | Agent SDK traces, OpenTelemetry GenAI spans |
| Application | API latency and errors, releases and feature flags, queue depth | OpenTelemetry, structured logs |
| Infrastructure | Database and vector store latency, provider rate limits, host health | Existing monitoring, provider status |
You do not need all four on day one. You do need a way to join them when a question crosses layers, which is the next section.
The join keys matter more than the dashboards
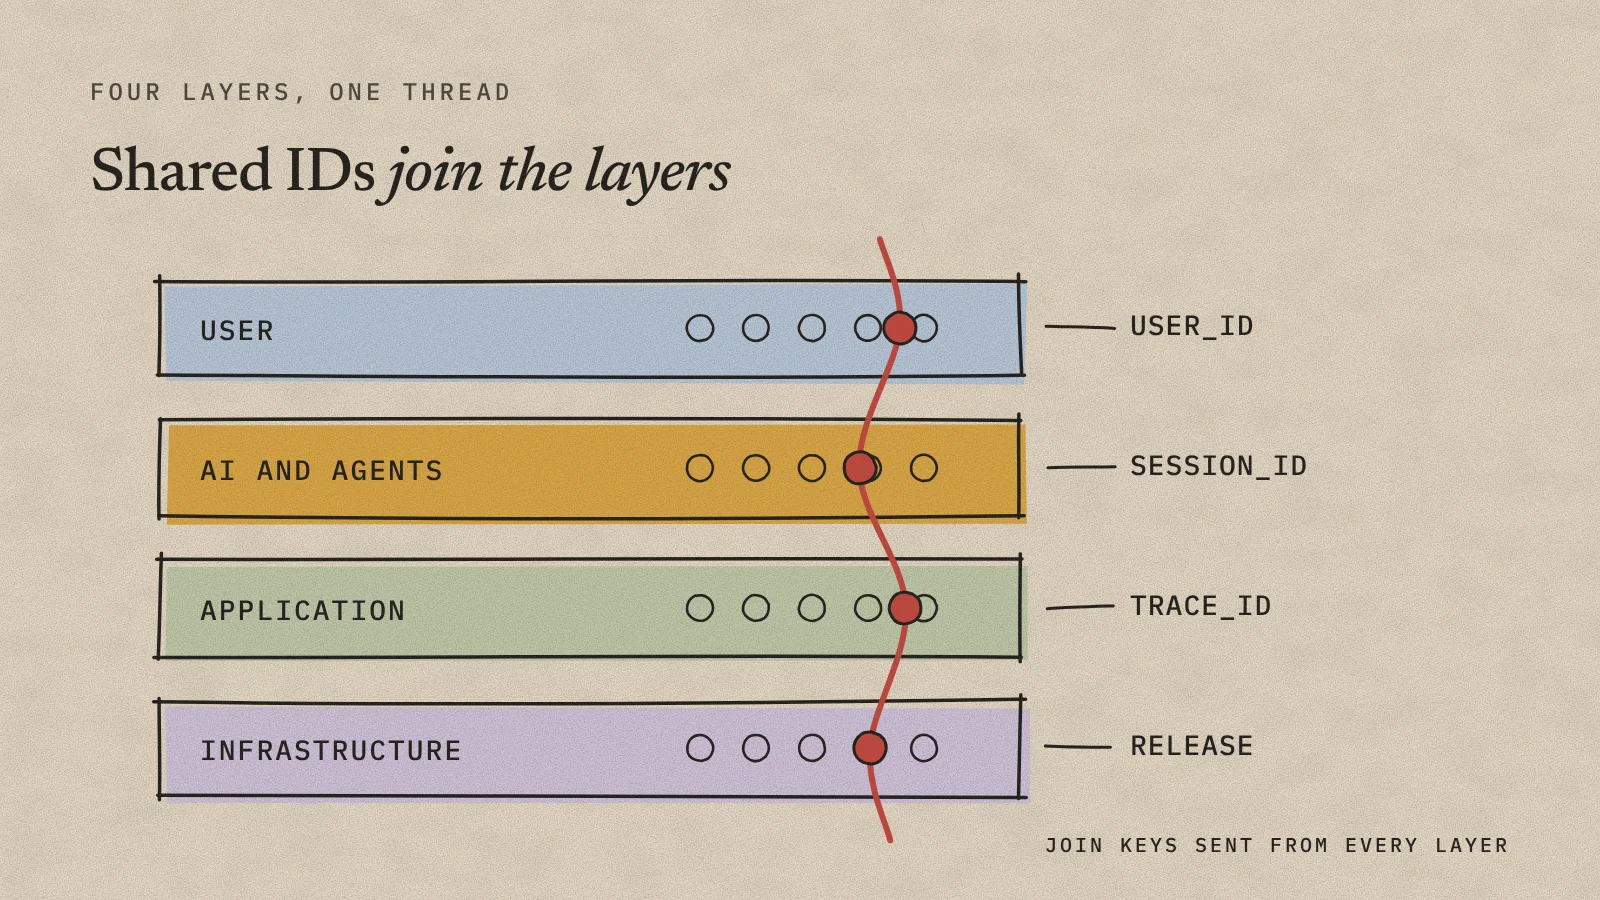
Cross-layer analysis only works if events from different layers share identifiers. Agree on these early and send them everywhere you can:
| Key | Set where | Lets you answer |
|---|---|---|
user_id (opaque, not an email) |
Frontend tracker, backend events, agent SDK | "Which users hit this failure?" |
session_id or conversation ID |
Frontend and agent SDK | "What did the user do before and after this answer?" |
trace_id |
Agent SDK or OpenTelemetry | "Which model and tool calls made up this run?" |
release or prompt version |
Deploy pipeline, agent config | "Did this start with a change we made?" |
workflow or feature name |
Agent config | "Which part of the product is this?" |
Without these, every investigation turns into lining up timestamps across tools by hand.
What to capture on every model and tool call
A practical minimum for each span:
- model and provider, and the parameters that matter (temperature, max tokens)
- input and output tokens, including cached and reasoning tokens where the provider reports them
- latency, and time to first token for streamed responses
- status and error type
- for tool calls: tool name, arguments, result size, and whether the result was empty
- the prompt or template version
- the join keys above
Prompts and responses are the most useful fields for debugging and the most sensitive. Decide up front whether you capture them in full, redact them, or encrypt them, and apply that rule in one place rather than per feature.
How the tool categories differ
Most teams already own some of this. It helps to be clear about what each category was built for:
- LLM tracing tools capture prompts, completions and evals well. They usually stop at the model boundary, so user behavior and the surrounding application are out of view.
- APM and infrastructure platforms see requests, hosts and databases well. Many now have LLM add-ons, but agent runs, tool chains and quality scores are newer territory for them.
- Product and web analytics see sessions and funnels. They have no view of what the model did inside a conversation.
The gap is rarely a missing chart. It is that the three views live in different places with different IDs, so nobody can follow one user from a click to a tool call and back.
A worked example
Here is how the support assistant case plays out once the layers are joined. The numbers are illustrative.
- User layer: sessions where the user asks the same question twice rose after Tuesday's release.
- Agent layer: in those sessions, the
lookup_ordertool returned an empty result far more often than before. - Application layer: Tuesday's release changed the order ID format sent to that tool.
- Cost: the agent retried the empty lookup before answering, so tokens per conversation went up as well.
None of these facts is hard to find on its own. The value is in getting from the first to the third without a meeting.
How to start
Start with one signal and add the next one when a real question needs it:
- Trace one AI feature. Add the SDK for your framework or point an existing OpenTelemetry exporter at a trace endpoint. Make sure
user_id,session_idand the prompt version are set. - Add an alert you will act on. Error rate or cost per run above a threshold for that one feature.
- Add the user layer when you need to know how failures affect behavior: the website or product tracker with the same
user_id. - Add evaluations when you need to know whether answers are good, not just fast: score a sample of live runs with a rubric.
Where Anosys fits
Anosys takes traces from the OpenAI and Anthropic SDKs and any OpenTelemetry source, events over a REST API, and user behavior from a website and product tracker, into one workspace. Fields you map once, such as user_id, work across all of them, so the worked example above is a filter rather than an export. Traces, evaluations, alerts and the AI Assistant all read from that same data.
To try it, follow Getting started with one AI feature.
Free plan, no credit card
Start observing your AI in production for free
Capture traces, cost and evaluation scores from your models and agents in a few minutes, with SDKs or OpenTelemetry.

