Observability for Monetizable AI: When Agents Start Clicking Ads
Someone asks an assistant to compare three pairs of headphones. The assistant opens review pages, loads whatever ads are on them, and may follow a sponsored link to a product page to check the price. The person reads a two-paragraph summary. They never saw the ads.
Two groups now have a measurement problem. Advertisers are paying for impressions and clicks that may have been made by software. And companies that put sponsored results inside their own AI answers need to show those advertisers what was shown, to whom, and what happened next, without the ad slots and tags that web advertising relies on.
This post covers both, with the events to record and the limits of what you can know.
Part 1: Advertisers and agent traffic
What has changed
Automated traffic is not new, and verification vendors have filtered crawlers and fraud for years. What's new is software acting for a real person with a real purchase intent, at least sometimes. That traffic falls into a few groups:
| Group | How it shows up | How confidently you can identify it |
|---|---|---|
| Declared agents | A published user agent string, or signed requests where the operator supports them | High for verified signatures, moderate for user agent strings |
| Automated browsers | A real browser driven by automation; may expose navigator.webdriver or other automation traits |
Medium; signals can be hidden |
| Agents in the user's own browser | Browser features and extensions acting inside a normal session | Low; often indistinguishable from the person |
| Humans | Everything else | By elimination |
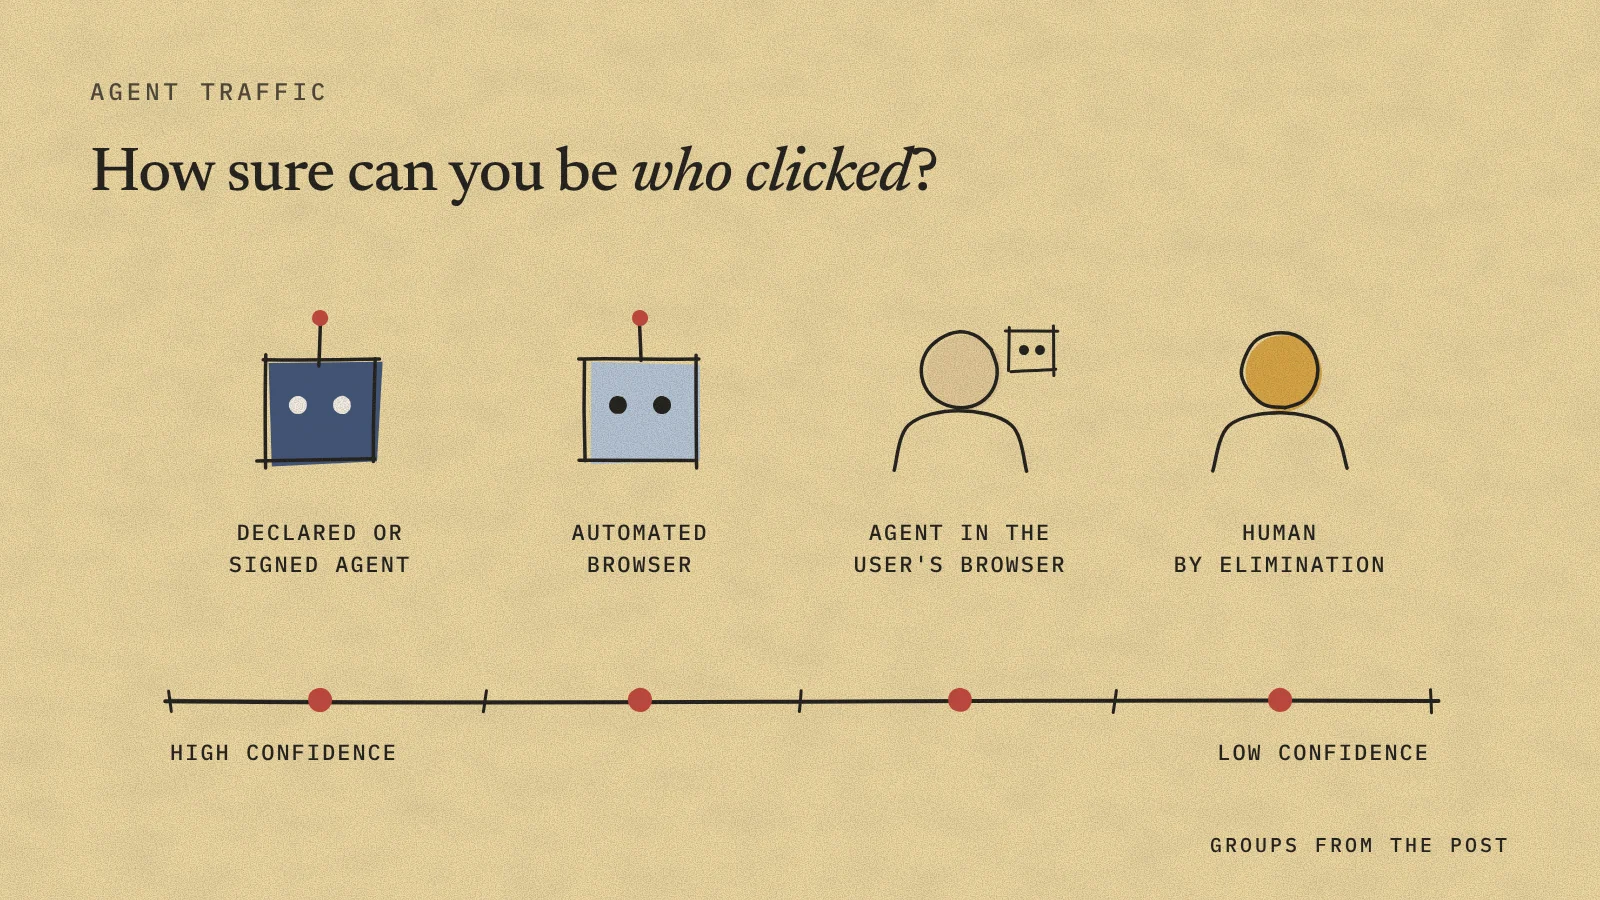
The useful goal is not perfect detection. It is to measure your ad traffic and conversions by group, so you can see how much spend lands in the first two groups and whether those visits ever convert.
What to record
Classify at the server or edge, where request headers are visible, and send one event per landing page request:
| Field | Example | Why |
|---|---|---|
cvs1 traffic group |
declared_agent, automation, unknown |
The classification you will report on |
cvs2 campaign or click ID |
from the landing URL | Joins to your ad platform's spend data |
cvs3 user agent family |
ChatGPT-User |
Shows which agents are visiting |
cvs4 landing path |
/products/x200 |
Which pages agents read |
cvb1 signature present |
true |
Whether the request carried a bot signature header |
A minimal classifier in Python:
Keep the agent list in configuration, not code: operators add and rename user agents often. A user agent string can be copied, and a signature header is only a claim until you verify it, which many CDNs and edge platforms can do for you. Add the browser-side tracker to the same pages from your shared footer to get engagement and scroll depth, which separate quick automated reads from human visits.
What to look at
- Share of paid clicks by traffic group, per campaign and per publisher.
- Conversion rate by group. If declared-agent clicks never convert, that is the evidence for a conversation with the ad network. If they do convert (because the agent's user later buys), that matters too.
- Engagement by group: engaged time and scroll depth on landing pages.
Keep the event-level records. A dispute or a make-good needs session-level detail, not a chart.
Part 2: AI products that show sponsored content
Why the usual ad stack doesn't fit
On a web page, an ad has a slot, a tag that fires when it renders, a click redirect and a conversion pixel. In an AI answer there is no slot: the sponsored item is part of generated text, the "click" might be a follow-up question, and the conversion might happen in a later session or through an API.
So you define the events yourself, record them server-side, and join them to the trace of the conversation that produced them.
Define the events
| Event | Fires when | Key fields |
|---|---|---|
sponsored_shown |
A response containing a sponsored item is delivered to the user | conversation ID, trace ID, advertiser, item, position in the answer |
sponsored_engaged |
The user clicks the item or asks about it | same IDs, action (click, follow_up) |
sponsored_converted |
Your backend records a purchase or sign-up attributed to the item | same IDs, value |
Record sponsored_shown from what was actually delivered, not from what the model was asked to include. Models sometimes drop or rephrase an item, and advertisers will ask for proof of delivery.
Join to the agent trace
If the assistant is traced with an agent SDK or OpenTelemetry, the trace_id field connects each sponsored event to the run that produced it: the user's question, the retrieval results, the tool calls and the final answer. That lets you answer questions advertisers and your own team will both ask:
- Which kinds of questions lead to sponsored items being shown?
- Does showing a sponsored item change answer quality scores or user feedback?
- Which advertisers' items are shown but never engaged with?
Two rules worth adopting early
- Label sponsored content clearly in the answer. Users and regulators expect it, and it makes "shown" unambiguous.
- Evaluate answers with and without sponsored items. Score a sample of conversations for relevance and accuracy. If sponsored items make answers worse, you will see it in retention before you see it in revenue.
Where Anosys fits
Anosys is not an ad verification service, and the classification above is yours to define. What it gives you is one place for the pieces: landing page events and browser engagement from the tracker, server-side events over the REST API, and agent traces from the OpenAI and Anthropic SDKs or OpenTelemetry, joined on the IDs you send. Dashboards, alerts (for example, a jump in agent share on a campaign) and evaluations all run on that data.
Free plan, no credit card
Tell agent traffic from human traffic
Track landing page sessions, engagement and conversions, and set your own rules for which visits look automated, all in one workspace.

